Reference table
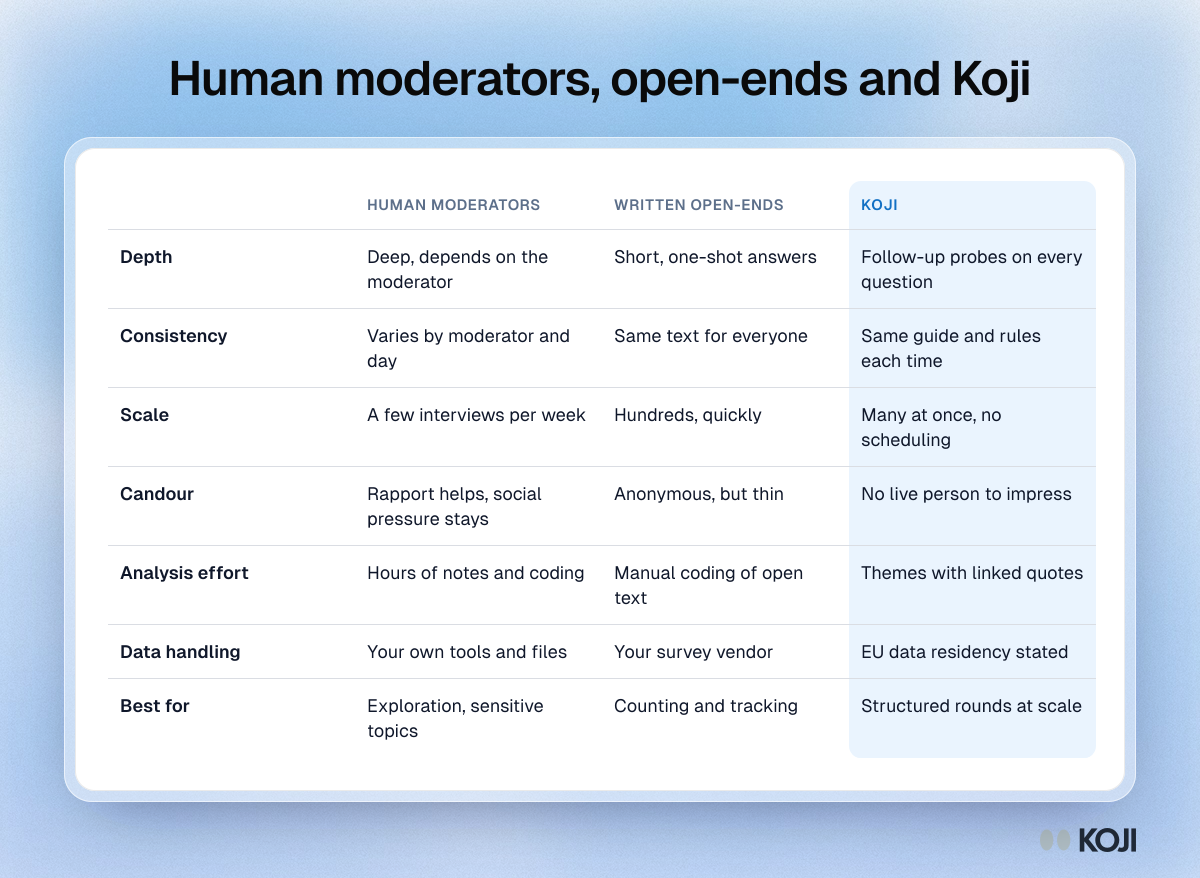
Human moderators, open-ends and Koji
How the three ways to collect the why compare
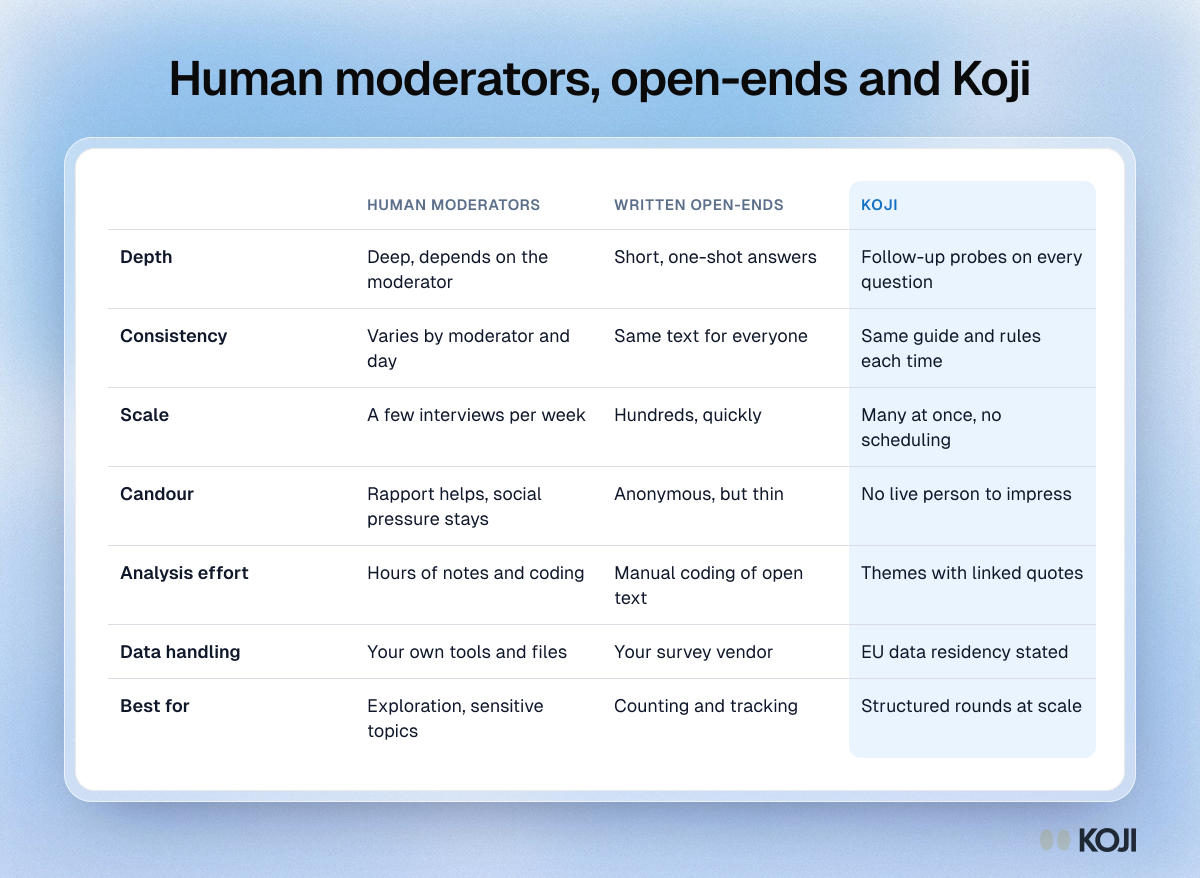
A comparison of human moderators, written survey open-ends and Koji across the criteria a UX research lead weighs when choosing how to collect the why behind behaviour. Human moderators remain the better choice for exploration and sensitive topics, while open-ends are the cheapest way to count things. Use it to decide which method suits each question in your pilot.
Where this appears
What's in this reference table
| Human moderators | Written open-ends | Koji | |
|---|---|---|---|
| Depth | Deep, depends on the moderator | Short, one-shot answers | Follow-up probes on every question |
| Consistency | Varies by moderator and day | Same text for everyone | Same guide and rules each time |
| Scale | A few interviews per week | Hundreds, quickly | Many at once, no scheduling |
| Candour | Rapport helps, social pressure stays | Anonymous, but thin | No live person to impress |
| Analysis effort | Hours of notes and coding | Manual coding of open text | Themes with linked quotes |
| Data handling | Your own tools and files | Your survey vendor | EU data residency stated |
| Best for | Exploration, sensitive topics | Counting and tracking | Structured rounds at scale |
Use this image
Free to use in your docs, decks and posts under CC BY 4.0, as long as you credit Koji with a link to this page. To embed it, paste this into your page:
html
<a href="https://www.koji.so/visuals/ai-moderator-vs-human-moderator-pilot-comparison"><img src="https://www.koji.so/visuals/ai-moderator-vs-human-moderator-pilot-comparison/ai-moderator-vs-human-moderator-pilot-comparison.png" alt="Table comparing human moderators, written open-ends and Koji on depth, consistency, scale, candour, analysis effort and data handling." width="1200" height="878" /></a>
<p>Source: <a href="https://www.koji.so/visuals/ai-moderator-vs-human-moderator-pilot-comparison">Human moderators, open-ends and Koji</a>, Koji</p>