How to Code Qualitative Data: Your First Coding Pass on 10 Interviews
The beginner path to coding qualitative data: one complete coding pass on ten interview transcripts, from first codes to checked themes, with a worked example.
Short answer: To code qualitative data for the first time, take 10 interview transcripts, read three of them start to finish, then label every passage that answers your research question with a short code (a few words that say what the passage means). Write each code's definition the moment you create it, code the remaining seven interviews against that list while adding new codes as needed, then merge, split and drop codes until 10 to 20 remain, and group those into 3 to 6 themes. That is one complete coding pass. It takes a weekend by hand, and it is enough to answer most product and customer research questions.
This page is the short beginner path: one pass, ten interviews, step by step. If you want the full method behind it, with Saldaña's first and second cycle coding methods and when to use each, read First and Second Cycle Coding. If you are building a codebook for a team, read How to Build a Qualitative Research Codebook.
What a code is
A code is a short label you attach to a passage of text so you can find, compare and count similar passages later. Johnny Saldaña, whose Coding Manual for Qualitative Researchers is the standard reference, defines it like this:
"A code in qualitative inquiry is most often a word or short phrase that symbolically assigns a summative, salient, essence-capturing, and/or evocative attribute for a portion of language-based or visual data." (Johnny Saldaña, The Coding Manual for Qualitative Researchers)
In practice, a code names one of four things:
- A problem someone describes ("rebuilds report every month")
- A behaviour ("checks the dashboard before standup")
- A reason or belief ("doesn't trust the numbers")
- A feeling ("dreads month end")
Saldaña is also clear about what coding is not: "Coding is not a precise science; it's primarily an interpretive act." Two careful people will code the same transcript a little differently. That is fine, as long as your codes are defined and you can show which passages sit behind each one.
Why 10 interviews is a good first set
Ten is small enough to code by hand and large enough to see patterns. The research on saturation, the point where new interviews stop adding new codes, backs this up:
- In a study of 60 interviews, Guest, Bunce and Johnson (2006) found that saturation occurred within the first twelve interviews, and the basic elements of the main themes were already present at six.
- Hennink, Kaiser and Marconi (2017) found code saturation, hearing the full range of issues, at nine interviews. Understanding what each issue meant to people took longer: 16 to 24 interviews.
- A systematic review by Hennink and Kaiser (2022) found that across 16 empirical tests, the interviews needed for saturation ranged from 5 to 24.
So ten interviews from one fairly similar group will show you most of the topics. They won't always explain them in depth. Treat your first pass as a map, and plan more interviews where the map is thin. For the full evidence, read Interview Sample Size Research.
Before you start: three decisions
- Write down your research question in one sentence. "Why do trial users stop using the product in week two?" Every coding decision is easier when you can ask "does this passage help answer that?"
- Choose inductive, deductive or both. Inductive means codes come from the data. Deductive means you start with a list (from your research question, a framework or a past study) and apply it. Most first studies use both: three to five starting codes from the question, then new codes as you find them. See Inductive vs Deductive Research.
- Pick a tool you already know. A spreadsheet with columns for participant, passage, code and note works well for ten interviews. You don't need dedicated software for a first pass.
Your first coding pass, step by step
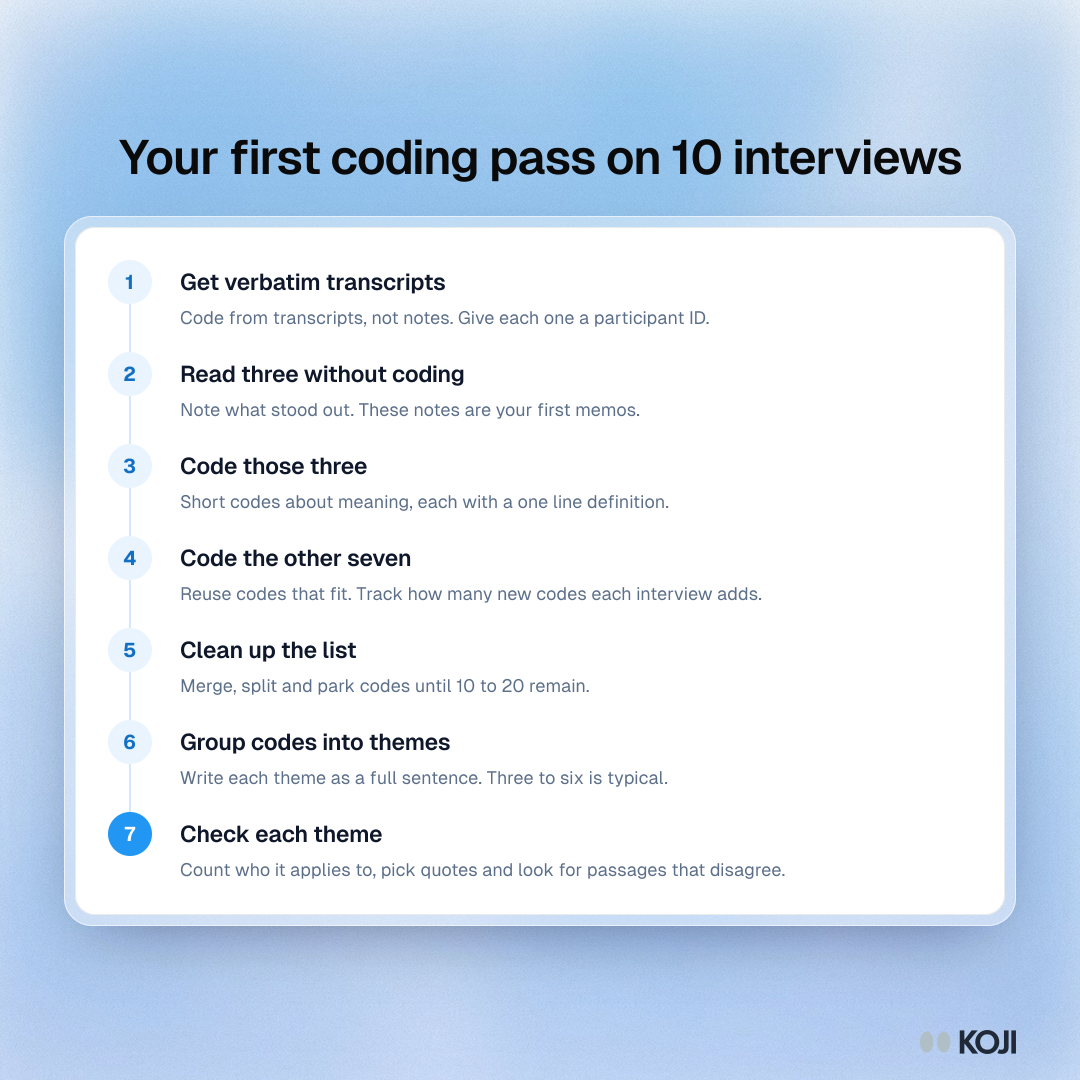
Step 1: Get clean, verbatim transcripts
Code from transcripts, not from notes. Notes are already your summary, so coding them codes your own words back to you. Give each transcript a participant ID (P01 to P10) and keep the date and any segment you care about (plan, role, company size) at the top.
Step 2: Read three transcripts without coding
Read the first three interviews straight through. Don't label anything yet. Jot down a few lines after each one: what stood out, what surprised you, what you want to check in the others. These notes are your first memos. See Analytic Memos for what to write.
Step 3: Code those three, passage by passage
Go back to the start of the first transcript. For each passage that relates to your research question, write a short code next to it. Rules that keep a first pass clean:
- Code the meaning, not the topic. "Pricing" is a topic. "Unsure what the paid plan adds" is a code you can act on.
- Keep codes short. Two to five words.
- One passage can carry two or three codes. People often say several things at once.
- Use the participant's own phrase when it says it better. "Human copy-paste machine" is a code worth keeping as is. That is in vivo coding.
- Write a one-line definition the first time you use a code. "Unsure what paid plan adds: the participant can't name a benefit of upgrading."
Expect 30 to 60 codes after three interviews. That is normal.
Step 4: Code the other seven against your list
Now code interviews four to ten. Before creating a new code, check whether one on your list fits. If it does, use it. If it nearly fits, either widen the definition (and recheck the passages you already coded) or create a new code. Keep a tally of how many new codes each interview adds. If interviews eight, nine and ten add almost nothing, your first pass has found most of what this group has to say.
Step 5: Clean up the list
With all ten coded, sort your codes and tidy them:
- Merge codes that name the same thing in different words.
- Split codes that hide two ideas.
- Drop or park codes that appear once and don't bear on the question. Park rather than delete when one person said something important. A single strong signal can matter.
- Rewrite definitions so someone else could apply them.
Aim for 10 to 20 codes. This is your first codebook.
Step 6: Group codes into themes
A theme is a pattern that answers part of your research question. It groups several codes into one sentence you could say to your team. Codes "rebuilds report monthly", "pulls from four tools" and "fixes dates by hand" might become the theme "Month-end reporting is manual work people fit around their real job."
Write each theme as a full sentence, not a label. "Reporting" tells nobody anything. Three to six themes is typical for ten interviews.
Step 7: Check every theme against the data
For each theme, count how many of the ten participants it applies to and pick two or three quotes that show it. Then look for passages that contradict it. A theme that holds up in seven of ten interviews, with a clear reason why the other three differ, is a finding. A theme that rests on one vivid quote is a hunch. Write down both kinds, and say which is which.
A short worked example
A founder interviews ten people who signed up for a trial and stopped using it. One participant, P04, says:
"I set it up on Monday, then I had to ask IT for SSO and by the time that came through I'd already gone back to the spreadsheet."
| Passage | Code |
|---|---|
| "I had to ask IT for SSO" | Blocked by IT access |
| "by the time that came through" | Setup outlasts motivation |
| "gone back to the spreadsheet" | Falls back to old tool |
After coding all ten, "Blocked by IT access" shows up in six interviews and "Falls back to old tool" in seven. Together with two related codes they become the theme: "Trials stall when setup needs someone else's approval, and the old tool fills the gap while people wait." That is specific enough to act on.
Common first-pass mistakes
- Coding from memory or notes instead of transcripts.
- Codes that only name a topic ("onboarding", "price"). You can't act on a topic.
- No definitions. After three interviews you will no longer remember what "friction" meant.
- Stopping at a code list. Codes are raw material. Themes are what you report.
- Only coding what confirms your idea. Look for the passages that disagree with your favourite theme.
When two people code
If two people share the coding, have both code the same two interviews on their own, then compare. Talk through every disagreement and fix the definition that caused it. If you want a number, a common rule of thumb from Miles and Huberman (1994), as summarised by O'Connor and Joffe (2020), is 80% agreement on 95% of codes. O'Connor and Joffe also note there is no universally accepted threshold, so the conversation about disagreements matters more than the score. See Inter-Rater Reliability.

Photo by Vitaly Gariev on Unsplash
How Koji helps
Coding by hand is worth doing once, because it teaches you what good codes look like. Koji takes over the slow parts when you run research often:
- Transcripts you can code from. Koji runs AI-moderated interviews by voice or text and asks follow-up questions on open answers, so you get full answers in the participant's words instead of a short line in a survey box.
- A first coding pass on every answer. After each interview, Koji codes each answer with short labels about what it means, and attaches the participant's exact words to each code. Koji checks each quote against the transcript and drops a code it can't ground in what the person said. Quotes stay in the participant's own language.
- Codes grouped across interviews. In the report, Koji groups similar codes from different interviews into themes for each question and shows how many interviews mention each one. With only a few interviews, the report says the themes may still change, much like the saturation research above.
- The evidence behind every finding. Open any finding to see the quotes behind it and go back to the transcript, which makes step 7 faster.
- Numbers where you need them. Add scale, choice, ranking or yes/no questions to the same interview, and Koji still codes the reasons people give.
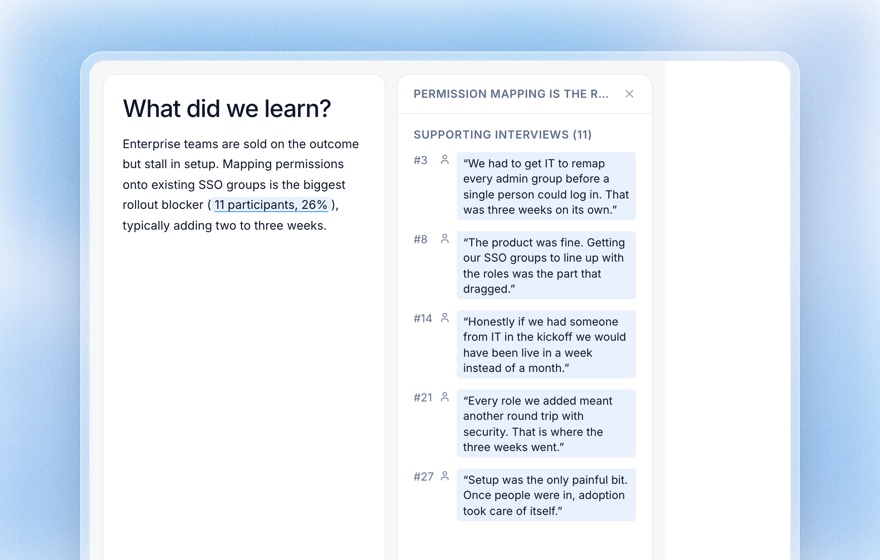
Treat Koji's codes and themes the way you would treat a colleague's first pass: read the quotes, rename what doesn't fit your question, and decide which themes matter. The interpretation is still yours.
Where to go next
- For the full method, read First and Second Cycle Coding.
- To turn your code list into a shared codebook, read How to Build a Qualitative Research Codebook.
- To analyse your themes across segments in a matrix, read Framework Analysis.
Related Resources
- First and Second Cycle Coding: Saldaña's coding methods and how codes become themes.
- How to Build a Qualitative Research Codebook
- Framework Analysis
- In Vivo Coding: using participants' own words as codes.
- Thematic Analysis Guide
- Structured Questions Guide
FAQ
How long does a first coding pass take? For ten interviews of 30 to 45 minutes, plan on a weekend. Reading and coding the first three takes longest, because that is where you build the code list. The last seven go faster.
How many codes should I end up with? Expect 30 to 60 codes after the first three interviews and 10 to 20 after you clean up. Those then group into three to six themes for a ten-interview study.
Should I code inductively or deductively? For a first study, both. Start with three to five codes from your research question, then add codes from the data as you find them.
Do I need software like NVivo or ATLAS.ti? Not for ten interviews. A spreadsheet with participant, passage, code and note columns is enough. Dedicated tools help once you have many studies or several coders.
What is the difference between a code and a theme? A code labels one passage. A theme is a pattern across many passages and participants that answers part of your research question, written as a full sentence.
Sources
- Saldaña, J. The Coding Manual for Qualitative Researchers. SAGE.
- Guest, G., Bunce, A., & Johnson, L. (2006). How many interviews are enough? An experiment with data saturation and variability. Field Methods, 18(1), 59–82.
- Hennink, M. M., Kaiser, B. N., & Marconi, V. C. (2017). Code saturation versus meaning saturation: How many interviews are enough? Qualitative Health Research, 27(4), 591–608.
- Hennink, M., & Kaiser, B. N. (2022). Sample sizes for saturation in qualitative research: A systematic review of empirical tests. Social Science & Medicine, 292, 114523.
- O'Connor, C., & Joffe, H. (2020). Intercoder reliability in qualitative research: Debates and practical guidelines. International Journal of Qualitative Methods, 19.
Further reading on the blog
- How to Analyze Customer Interview Data: A Complete Guide — You ran the interviews. Now what? Here is a step-by-step process for turning raw transcripts into clear, actionable insights your team will
- How to Analyze User Interview Data: A Complete Guide (2026) — You ran the interviews. Now what? This step-by-step guide covers how to turn raw interview data into clear, actionable insights — with and w
- How to Conduct Remote User Interviews: The Complete Guide (2026) — Remote user interviews are now the default for most research teams. This guide covers everything — from recruiting and scheduling to running
Related Articles
Affinity Mapping: Organize Qualitative Data Into Themes
Learn how to use affinity mapping to group qualitative research data into meaningful clusters and uncover actionable patterns.
How to Analyze Open-Ended Survey Responses with AI (2026 Guide)
Stop manually coding free-text survey responses. Learn how AI analyzes open-ended answers at scale — surfacing themes, sentiment, and quotes in minutes, plus why an AI interview captures 10x more depth than any survey can.
AI Auto-Tagging for Customer Interviews: Code 100 Interviews in Minutes
How AI auto-tagging compresses 40+ hours of manual qualitative coding into minutes. Covers the two-cycle coding approach Koji uses (descriptive cycle-1 + axial cycle-2), the difference between auto-tagging and thematic analysis, building a codebook the AI respects, and how to validate AI-generated tags against your standards.
AI-Generated Insights
Discover what analysis Koji automatically produces for each interview — themes, sentiment, key quotes, and findings.
AI Transcription for Research Interviews: Speed Up Analysis by 10x
Learn how AI transcription transforms research interviews — from audio to analysis in minutes. Covers accuracy, speaker identification, theme extraction, quality scoring, and how Koji automates the entire pipeline.
Analytic Memos in Qualitative Research: What to Write and When
Analytic memos are short notes where qualitative analysis actually happens. The five types, what to write in one, an example, when to write them and how memos tell you when you have enough interviews.
Codes, Categories and Themes: What Is the Difference in Qualitative Analysis?
Codes label excerpts, categories group codes and themes make a claim about meaning. Definitions, one worked example, and five tests for telling a real theme from a topic.
Customer Feedback Analysis: How to Turn Raw Input Into Actionable Insights
A complete guide to analyzing customer feedback — from coding and theming to prioritizing findings and sharing insights with stakeholders. Includes how AI compresses weeks of manual analysis into hours.
Diary Studies: The Complete Guide to Longitudinal User Research
Learn how to design, run, and analyze diary studies that capture real user experiences in context. Includes how AI interviews complement diary research at scale.
First and Second Cycle Coding: Saldaña's Coding Methods Explained
The two cycles of qualitative coding from Saldaña's Coding Manual: first cycle methods, second cycle methods such as pattern coding, a worked example and how to choose.
Generating Research Reports
Create comprehensive aggregate reports across all your interviews — including summaries, themes, recommendations, and statistics.
Grounded Theory in Qualitative Research: A Practical Guide
A practical guide to grounded theory methodology — how to collect, code, and analyze qualitative data to develop theory from the ground up, and how AI-powered tools accelerate the iterative analysis process.
How to Quantify Qualitative Data Without Overclaiming
How to turn coded interview themes into counts you can defend: count people not mentions, give the base, add the uncertainty, and know when a survey is the better tool.
In Vivo Coding: Using Participants' Own Words as Codes
What in vivo coding is, how to do it step by step, how it compares with descriptive and other first cycle methods, and the mistakes that weaken it.
Inter-Rater Reliability in Qualitative Research: A Practical Guide to Coding Agreement
Learn how to measure inter-rater (intercoder) reliability in qualitative research using Cohen's kappa and Krippendorff's alpha, what thresholds count as reliable, and how AI-native tools make consistent coding the default.
Presenting Research Findings to Stakeholders
Learn how to present qualitative research findings effectively — from storytelling with data and using participant quotes to structuring reports for executives, product teams, and designers.
Rapid Qualitative Analysis: How to Get From Interviews to Findings in Days
Rapid qualitative analysis replaces line-by-line coding with summary templates and a participant-by-topic matrix. How the Hamilton method works, what the evidence says, and how to run one.
How to Build a UX Research Repository: The Complete Guide
A research repository transforms scattered insights into a searchable organizational asset. Learn how to build one that teams actually use.
Singleton Themes: Why One-Off Comments Are the Only Estimate You Have of What You Missed (2026)
Good-Turing says the chance the next respondent raises something new is the singleton count divided by total mentions. Every synthesis step deletes singletons first.
The Complete Guide to Thematic Analysis
Learn how to systematically analyze qualitative data using Braun and Clarke's six-phase thematic analysis framework.
Theme Co-Occurrence: Finding the Problems That Travel Together (2026)
The theme pair that appears together more than chance predicts is usually closer to the real problem than either theme alone. Rank pairs by observed over expected, not by raw co-occurrence, and count once per participant.
Theme Dispersion: Why 47 Mentions Can Mean Three Customers (2026)
A mention count hides how many people produced it. 47 mentions can be 41 customers or 3. Report distinct speakers beside every count, choose your dispersion unit deliberately, and use Gries DP when the decision is expensive.
Turning Interviews Into Insights: From Raw Data to Action
A complete guide to transforming raw interview transcripts into structured, actionable insights — covering manual analysis, AI-assisted workflows, and frameworks for prioritizing findings.
The Definitive Guide to User Interviews
Everything you need to plan, conduct, and analyze user interviews that produce actionable research insights.
Verbatim Analysis: How to Code and Analyze Open-Ended Responses at Scale (2026)
Verbatim coding turns messy open-ended answers into countable themes — but manual coding is slow, expensive, and bias-prone. Learn the code-frame workflow, the manual vs AI tradeoff, and how Koji auto-codes verbatims and captures the depth a survey verbatim never could.
Viewing Interview Transcripts
How to read, navigate, and get value from your interview transcripts in Koji.