Structured Questions in AI Interviews
Mix quantitative data collection — scales, ratings, multiple choice, ranking — with AI-powered conversational follow-up in a single interview.
Structured questions are what make Koji fundamentally different from both traditional surveys and standard interview tools. They let you embed quantitative data collection — scales, ratings, multiple choice, ranking — directly inside a natural AI-powered conversation. Every structured response is automatically followed up by the AI, so you capture both the number and the reasoning behind it in a single interaction.
The Problem with Traditional Approaches
Research has traditionally forced a painful choice: run a survey to collect structured, chartable data (but miss the "why"), or run an interview to understand motivations and context (but lose the ability to aggregate and compare across participants). Most teams end up running both — doubling the cost, timeline, and participant burden.
Koji's structured questions eliminate that tradeoff. A single AI interview captures quantitative metrics that aggregate into charts and distributions, alongside rich qualitative context from conversational follow-up. You get the benchmarkable numbers your stakeholders want and the deep human insight your research needs — from the same conversation.
How It Works
When you add a structured question to your study, two things happen during every interview:
-
The participant provides a structured response — a number on a scale, a selected option, a ranked list, or a yes/no answer. In text mode, this appears as an interactive widget (slider, radio buttons, checkboxes, drag-to-rank) embedded naturally in the chat. In voice mode, the AI handles everything conversationally — it asks the question, hears the answer, and extracts the structured value.
-
The AI immediately probes for the "why" — based on the response, the AI follows up with contextual probing. A participant who gives a low satisfaction score gets different follow-up questions than one who gives a high score. This probing is what transforms a data point into an insight.
Every response is captured twice: as a structured value (the number, choice, or ranking) for aggregate reporting, and as qualitative context from the follow-up conversation. When you generate a report, structured questions produce charts — distribution charts for scales, bar charts for choices, ranked lists for rankings — alongside AI-synthesized qualitative insights explaining the patterns in the data.
The Question Types
Koji supports seven question types, each suited to a different kind of data:
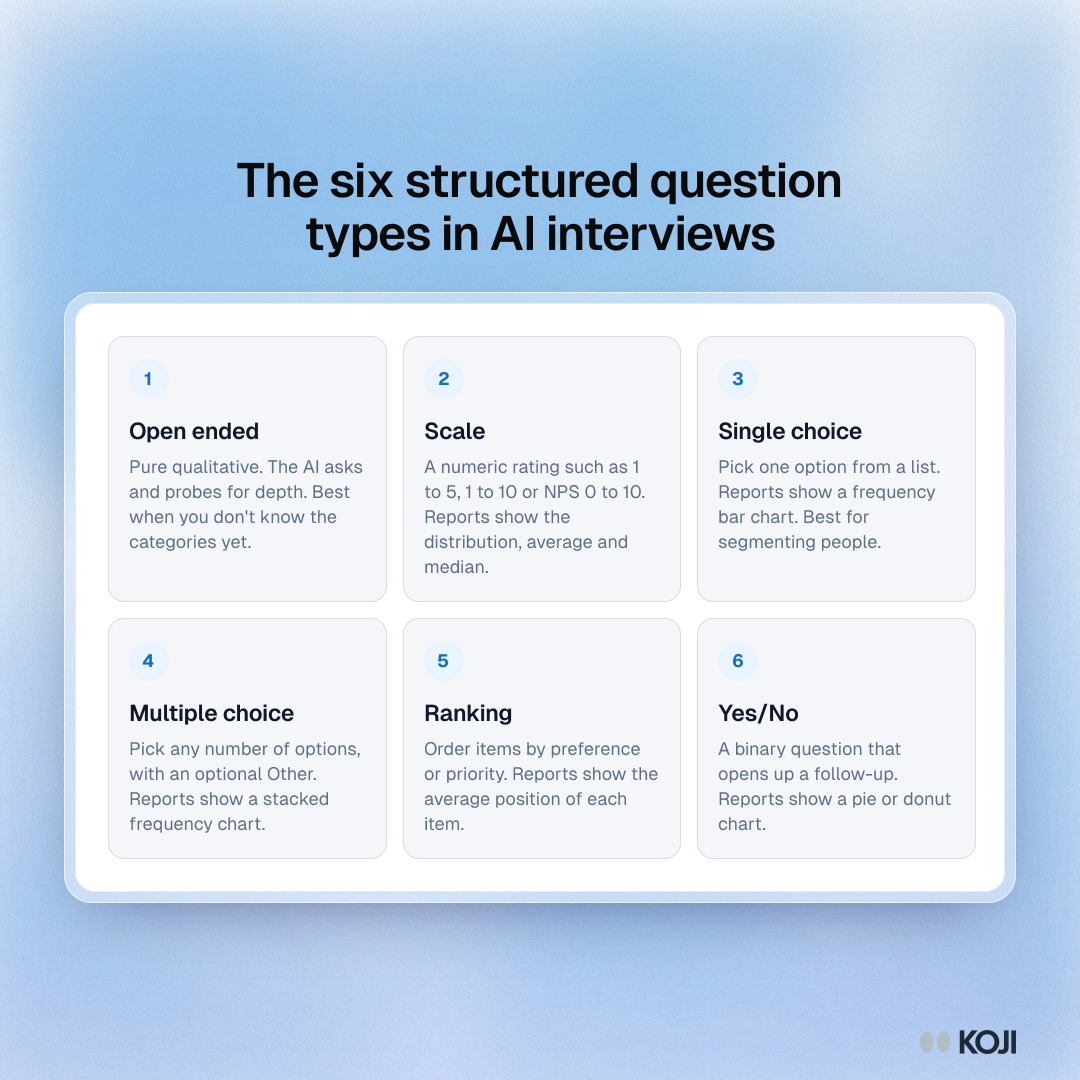
Open Ended — The default question type. Pure qualitative, no structured value. The AI asks the question and probes for depth. Best for exploratory discovery where you don't yet know the right categories or scales.
Scale — A numeric rating (e.g., 1–5, 1–10, NPS 0–10). You define the range and can add labels for the endpoints (e.g., "Very Unlikely" to "Very Likely"). Reports show a distribution chart with average and median. Best for NPS, CSAT, satisfaction scores, and any metric you want to track over time.
Single Choice — Pick one option from a list. Reports show a frequency bar chart. Best for segmentation questions like "which of these describes your role?" or "which feature do you use most?"
Multiple Choice — Pick any number of options from a list. You can also enable an "Other" free-text option for responses you didn't anticipate. Reports show a stacked frequency chart. Best for "what challenges do you face?" (select all that apply).
Ranking — Order a list of items by preference or priority. In text mode, participants drag items into their preferred order. Reports show average position for each item. Best for feature prioritization and preference ordering.
Yes/No — A binary question. Reports show a pie or donut chart. Best for confirmation questions ("Have you tried X?") that open up more nuanced follow-up conversation.
Price Test (Gabor-Granger): finds the price that earns the most. Describe what you're pricing and enter 3 to 10 prices. Each participant rates how likely they are to buy at one price at a time, and Koji moves up or down your list until it finds the most they would pay, then asks why. Reports show the share who would buy at each price, what each price earns per person, and the price that earns the most. Works in text and voice interviews, not on phone calls. See Set Up a Price Test in Koji.
Anchor Probing: The Power of Scale Questions
Scale questions have a unique probing feature called anchor probing. When enabled, after a participant gives their rating, the AI asks a question like:
"You said 7 — what would need to change to make it a 9 or 10?"
This technique is powerful because it:
- Surfaces specific, actionable improvements rather than vague dissatisfaction
- Anchors the follow-up in the participant's own evaluation framework
- Reveals the gap between current experience and ideal experience
- Produces insights that map directly to product or service improvements
Anchor probing works on any scale question and is especially valuable for NPS, satisfaction, and likelihood-to-recommend metrics. You can enable it in the probing configuration for any scale question in the brief editor.
Step-by-Step Guide
-
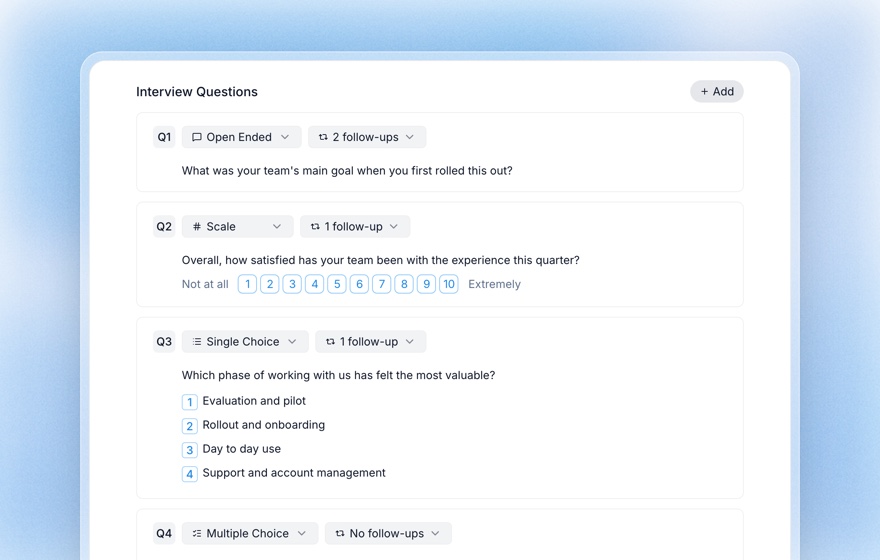
Open your study's research brief From your study dashboard, open the research brief editor and navigate to the Questions tab. For details on the editor, see Editing the Brief Manually.
-
Add a new question Click the Add Question button. Enter your question text and select the question type from the dropdown.
-
Configure type-specific options For Scale questions, set the min/max values and optional endpoint labels (e.g., "Very Unlikely" to "Very Likely"). For Choice or Ranking questions, add your option list. You can enable "Allow Other" on choice questions to capture write-in responses.
-
Set AI probing depth Each question has a probing configuration. Set the maximum number of follow-up questions the AI will ask (0 = no probing, 1–3 = increasing depth). You can add specific probing instructions, like "If the participant gives a low score, ask what would need to change." For scale questions, consider enabling anchor probing.
-
Order your questions Drag questions into the sequence that makes sense for the conversation flow. Open-ended discovery questions work well at the start; structured ratings fit naturally toward the end once rapport is established.
-
Publish your study Once you're satisfied with your question mix, publish the study as normal. Question IDs are assigned at publish time and remain stable across the life of the study, ensuring accurate data aggregation.
"Prefer Not to Answer"
Every structured question includes a "Prefer not to answer" option. Participants can always skip any question they're uncomfortable answering. Skipped responses are tracked separately from answered responses in your report data, so your aggregate statistics (averages, distributions, frequencies) remain accurate and are not skewed by missing data.
This is deliberate — research ethics require that participants never feel forced to answer any question. The "prefer not to answer" option is always available and cannot be disabled.
Key Things to Know
-
Text vs. voice behavior: In text mode, quantitative questions render as interactive widgets — sliders, radio buttons, checkboxes, or drag-to-rank lists. In voice mode, all questions are handled conversationally and the AI extracts structured values from spoken answers. Both modes capture the same data.
-
It's a conversation, not a survey: Unlike traditional survey tools, structured questions in Koji are embedded within a natural, flowing AI conversation. The AI builds rapport, asks open-ended questions for context, and then introduces structured questions at natural conversation points. Participants experience a conversation with data capture moments, not a form with chat bolted on.
-
Question IDs are stable: Each question has a stable identifier assigned at publish time that flows through from the brief to the interview to the report. This means your reports accurately aggregate data across all interviews, even if question text is lightly edited.
-
AI probing follows structured answers: After a participant selects their answer via widget (or speaks it in voice mode), the AI adapts its follow-up based on what they selected. A participant who gives a low satisfaction score gets different follow-up questions than one who gives a high score.
-
Reports automatically visualize structured data: When you generate a research report, each structured question gets the right visualization: distribution charts for scales, bar charts for choices, ranked lists for rankings — no manual chart-building required.
-
Sections help with longer studies: If your study has many questions, use section grouping to organize them (e.g., "Background," "Product Experience," "NPS"). This helps the AI present questions in a coherent, conversational arc.
Tips and Best Practices
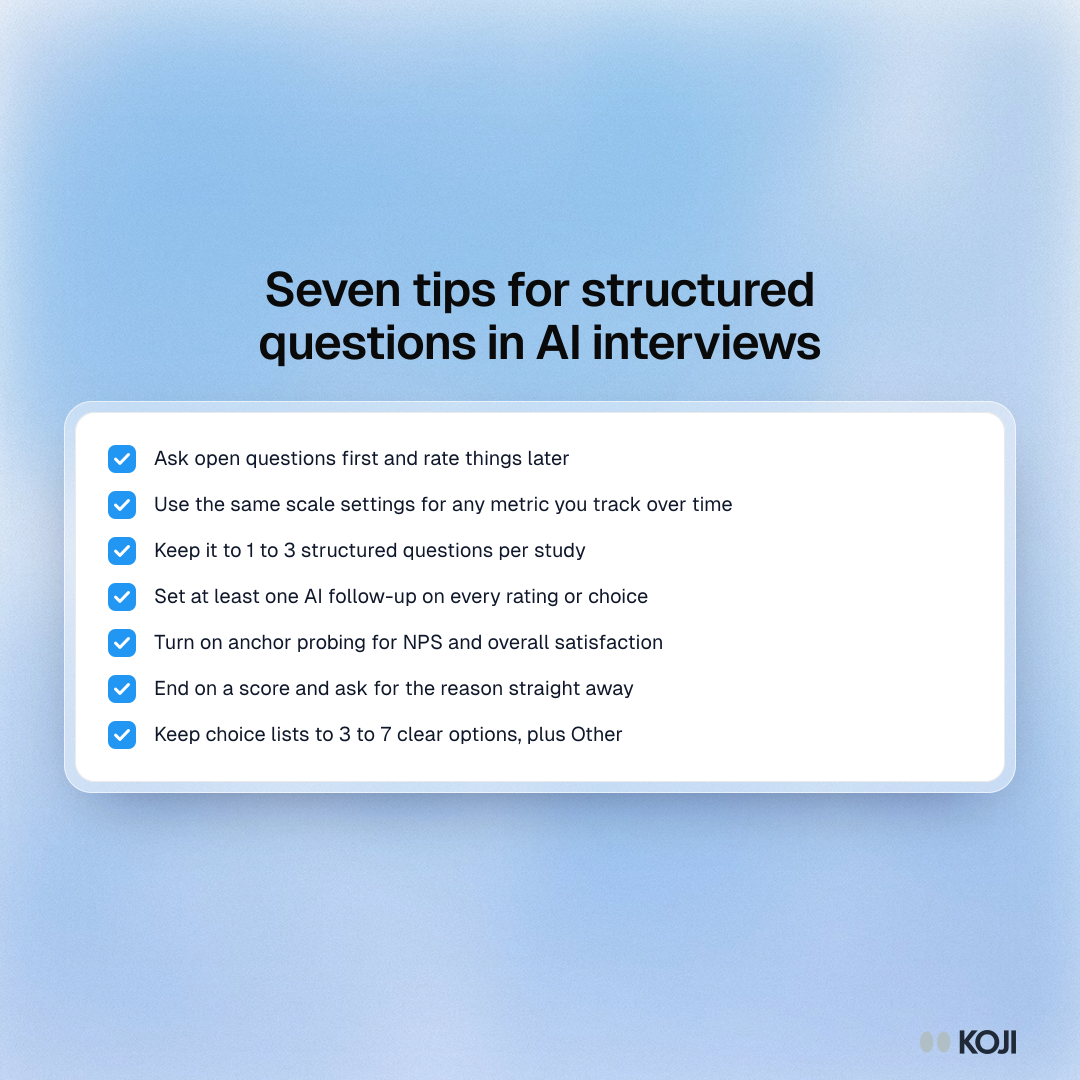
- Put qualitative questions first: Build rapport and let participants share naturally before asking them to rate anything. Open-ended questions early in the interview produce richer context for the structured answers that follow.
- Use scale questions for benchmarks: If you're tracking a metric over time (NPS, CSAT, feature satisfaction), use a Scale question with consistent parameters so you can compare across studies.
- Don't over-structure: Resist the urge to turn every question into multiple choice. Structured questions are most powerful when used sparingly — they anchor key metrics while open-ended questions carry the qualitative depth. Most studies benefit from 1–3 structured questions mixed with several open-ended ones.
- Always enable probing on quantitative questions: A scale or choice question without AI follow-up is just a survey. The real value is in the "why" — configure at least one follow-up for every quantitative question.
- Enable anchor probing on key scales: For your most important scale questions (NPS, overall satisfaction), turn on anchor probing. The "what would change your score?" follow-up produces some of the most actionable insights in any study.
- Mix and match for richer reports: A study that ends with an NPS score and immediately probes the reason behind it gives you both the benchmarkable number and the insight — something no traditional survey tool can deliver.
- Keep choice lists focused: For single and multiple choice questions, aim for 3–7 clear, mutually exclusive options. More than that and participants spend too much time reading instead of thinking. Use "Allow Other" as a catch-all.
Related Articles
- Set Up a Price Test in Koji: every price test setting, and how to read the result
- Understanding the Research Brief — how structured questions fit into the overall brief
- Editing the Brief Manually — using the question editor to configure structured questions
- Text Interview Experience — how structured questions appear as interactive widgets
- Voice Interview Experience — how structured questions work in voice mode
- Choosing a Methodology — which methodologies pair best with structured data capture
- Publishing Your Study — how question IDs are assigned at publish time
- Generating Research Reports — how structured data becomes charts and visualizations
- AI-Generated Insights — how qualitative follow-ups are synthesized
Frequently Asked Questions
Q: Do structured questions work in both voice and text mode? A: Yes, but they work differently. In text mode, quantitative questions appear as interactive widgets — sliders, radio buttons, checkboxes, or drag-to-rank lists. In voice mode, the AI handles all questions conversationally and extracts structured values from spoken responses. Both modes capture identical data for reporting.
Q: Can I mix structured and open-ended questions in the same study? A: Absolutely — this is the recommended approach. Open-ended questions explore freely and build rapport; structured questions anchor key metrics. A typical study might start with 2–3 open-ended discovery questions, then include 1–2 scale or choice questions toward the end.
Q: How does the AI use structured question data in reports? A: When you generate a research report, each structured question produces a chart (distribution for scales, bar chart for choices) alongside AI-synthesized qualitative context from follow-up conversations. You get both the numbers and the reasoning in a single report.
Q: Can participants skip a structured question? A: Yes. A "Prefer not to answer" option is always available on every structured question and cannot be disabled. Skipped questions are tracked separately from answered questions in the report, so your aggregate data stays accurate.
Q: How many structured questions should I include in a study? A: Most studies benefit from 1–3 structured questions mixed with several open-ended ones. More than 5 structured questions can make the conversation feel survey-like, which reduces the qualitative depth participants share.
Q: What is the difference between structured questions in Koji and a regular survey? A: In a regular survey, structured questions stand alone — participants select an answer and move on. In Koji, every structured question is embedded in a natural AI conversation and followed by intelligent probing. The AI adapts its follow-up based on the specific response given, capturing both the quantitative data point and the qualitative reasoning behind it. It's the difference between knowing your NPS is 7 and knowing your NPS is 7 because the onboarding was confusing but the support team was excellent.
Q: What is anchor probing? A: Anchor probing is a feature specific to scale questions. After a participant gives a rating, the AI asks what would need to change to improve that rating (e.g., "You said 7 — what would make it a 9?"). This surfaces specific, actionable insights about the gap between current and ideal experience. You can enable it in the probing configuration for any scale question.
Further reading on the blog
- The 11 Best AI Survey Tools in 2026 (Ranked & Reviewed) — We tested 11 AI-powered survey platforms head-to-head — from AI question generation to automatic open-ended analysis to fully AI-moderated c
- Koji vs Insight7: AI Customer Research Platforms Compared (2026) — Insight7 analyzes recorded calls. Koji runs the interviews itself — AI-moderated voice conversations from €3 per interview at the annual rate. Compare features, prici
- Koji vs Listen Labs: AI Interview Platforms Compared (2026) — Listen Labs raised $69M and powers enterprise research at brands across the Fortune 500. Koji is the accessible AI-native alternative starti
Related Articles
Adaptive AI Interviews: Branching Logic That Personalizes Every Question
How AI-moderated interviews replace static survey branching with dynamic, conversational follow-ups. A practical guide to designing adaptive interview flows with Koji.
Agent Trajectory Evaluation: How to Judge Multi-Step AI Agents with Real Users (2026)
Outcome-only scoring hides where AI agents actually break. Learn how to evaluate the full trajectory - every reasoning step, tool call, and hand-back to the user - using step-level rubrics and real participant evidence.
AI-Assisted Answers: What to Do When Participants Let an LLM Write Their Open-Ends
A real, eligible participant pasting your open-ended question into a chatbot is a validity problem, not a fraud problem. Here is what the evidence shows, why homogenization is the expensive part, and how to design questions a generic answer cannot survive.
AI Auto-Tagging for Customer Interviews: Code 100 Interviews in Minutes
How AI auto-tagging compresses 40+ hours of manual qualitative coding into minutes. Covers the two-cycle coding approach Koji uses (descriptive cycle-1 + axial cycle-2), the difference between auto-tagging and thematic analysis, building a codebook the AI respects, and how to validate AI-generated tags against your standards.
Conversation Memory and Long-Session Degradation: Why AI Interviews Get Worse After Turn 20 (2026)
AI moderators lose the thread in long conversations. The evidence, the four degradation symptoms, the session budget framework, and how to test your own moderator before it costs you a study.
AI Explainability Testing: How to Find Out Whether Your Explanations Actually Help Users (2026)
Explanations that users rate highly often fail to improve their decisions — and in one 3,800-person experiment, the more transparent model made people worse at catching its mistakes. This guide covers the four outcome measures that separate a useful explanation from a satisfying one, and how to test yours.
Acceptance Criteria for AI Features: How to Define "Good Enough to Ship" (2026)
Traditional acceptance criteria are binary and per-case; AI features fail probabilistically, so the same approach produces a checklist nobody can sign. This guide shows how to write distributional acceptance criteria, weight false positives against false negatives by user cost, and gather the user evidence that makes a ship decision defensible.
AI Incident Postmortems: How to Investigate Model Failures with User Evidence (2026)
Logs tell you what your model output. They cannot tell you what it cost the person on the other end. A practical guide to running blameless AI incident postmortems with real user evidence - and meeting the reporting clocks that now apply.
AI Interview Best Practices: 14 Rules for Running High-Quality AI-Moderated Customer Research
A practical playbook for running AI-moderated customer interviews that produce research-grade insights — 14 concrete rules covering brief design, question writing, probing depth, mode selection, recruiting, and analysis.
AI Interviewer Tuning: How to Get Research-Grade Voice Interviews
A complete playbook for tuning Koji's AI interviewer — company context, probing depth, structured questions, and interview mode — to deliver interviews indistinguishable from a human researcher.
AI Model Cards and User Disclosure: Documenting Intended Use, Limitations, and What You Tell People (2026)
A practical guide to model cards, system cards, and user-facing AI disclosure — what belongs in each section, what the EU AI Act's Article 50 has required since 2 August 2026, and how to source the Limitations section from real user research instead of guesswork.
Model Version Drift: What Happens to Your Research When the AI Changes Mid-Study (2026)
When the model behind your AI moderator or analyst is upgraded, your measuring instrument changed. The evidence, the three layers of drift, the bridge sample method, and how to make model version part of your method section.
AI Note-Taker for User Interviews: Stop Manually Transcribing and Start Acting on Insights
How AI note-takers transform user research — from passive transcription tools that just record meetings to active research moderators that capture, structure, and analyze every conversation automatically.
How Koji's AI Follow-Up Probing Works: Going Deeper Than Any Survey
Understand how Koji's AI interviewer automatically asks follow-up questions to go deeper on every answer — and how to configure probing depth, custom instructions, and anchor behavior for scale questions.
AI Customer Research for AI Product Companies: How to Research a Nondeterministic Product
How teams building AI and GenAI products run user research when the product gives different answers every time: trust calibration, degraded states, model-upgrade regressions, and usage-based pricing.
AI Customer Research for Construction and the Built Environment
How construction tech and building-products companies research a fragmented, field-based market: voice interviews from the job site, the split owner-GC-sub buying chain, and why office-bought software dies in the field.
AI Customer Research for Cybersecurity Companies: Interview CISOs and Practitioners at Scale
How security vendors run buyer and practitioner research with AI-moderated interviews that respect confidentiality, survive the alert queue, and reach the whole buying committee.
AI Customer Research for HR Tech and People Ops Software
How HR tech vendors research a market where the buyer is not the user: three-audience studies across HR leaders, managers and employees, cycle-timed fieldwork, and admin burden nobody measures.
How to Analyze AI-Moderated Interview Results
A complete guide to analyzing interview results from AI-moderated sessions — read the quality score, the per-question structured answers, the auto-generated themes, and the cross-interview report. With Koji, analysis is done before you open the transcript.
Authority Gradient: Why Nobody on Your Team Told You the Study Was Wrong
Everyone guards the bias between moderator and participant. Almost nobody guards the gradient between researcher and stakeholder - the one that decides whether the right study gets run at all.
Automation Surprise in Research: When Your Pipeline Is Not Doing What You Think (2026)
Aviation human factors has studied mode error for forty years. Your research pipeline has 128 configurations and you chose two of them. Here is the import.
The Average of a Ratio Is Not the Ratio of the Averages (2026)
Averaging percentages across segments, or averaging through a curve, produces a number that describes nobody. Two distinct failure modes, two different fixes.
B2B User Research: How to Interview Enterprise Customers Without the Scheduling Nightmare
B2B user research is harder than consumer research — limited access, complex stakeholders, and brutal scheduling constraints. This guide explains how to run deep, qualitative enterprise research at scale using AI-moderated interviews.
The Barnum Test: How to Tell If a Research Finding Says Anything About Your Users (2026)
A research finding only describes your users if a team with different users would reject it. Use a forced choice against a plausible decoy, not a stakeholder rating.
Best AI Interview Software in 2026: 9 Platforms Compared
A side-by-side review of the leading AI interview platforms in 2026 — Koji, Listen Labs, Strella, Outset, Marvin, Conveo, Glaut, Feedbk, and User Intuition. Pricing, modality, recruitment, analysis, and the right tool for each use case.
The Case Definition: The Decision That Fixes or Breaks Every Issue Count (2026)
Before you count affected users you have to decide who counts. Epidemiology has a century of discipline on this, including one rule almost every product team breaks.
Choice and Ranking Questions in AI Interviews: Capture Preference Data at Scale
Learn how to use single choice, multiple choice, ranking, and yes/no questions in Koji AI interviews — with automatic report charts that show preference distributions across all your participants.
Trust the Delta, Not the Level: Common-Mode Bias in Research (2026)
A bias that hits every arm equally cancels when you subtract and survives intact in any absolute number. How to tell which kind of bias you have.
Did the Feature Cause the Complaint? A Causality Grading Method for Product Feedback
A complaint that names a feature is a hypothesis about that feature, not evidence about it. Four tests, two scales, and the rechallenge your feature flags already give you for free.
Why Complaint Counts Cannot Become Rates (And What to Compute Instead)
A count of complaints has no denominator, so it can never become a rate. Here is the arithmetic that works anyway, borrowed from fifty years of safety surveillance.
The Composite Sample Problem: Why Your Aggregate Score Hides the Account on Fire (2026)
Combining many responses into one number gives you an unbiased mean and destroys the between-unit variance. Here is what compositing costs you, and the design that keeps the mean and the outlier.
Your Consent Form Is Part of the Instrument (2026)
Consent and confidentiality wording is not administrative text sitting outside your study. A survey experiment shows it changes who finishes - and it filters exactly the people you need on a sensitive topic.
Conversational Surveys: How AI Interviews Replace Forms (2026)
A complete guide to conversational surveys — what they are, how they differ from chatbot surveys and AI interviews, why they produce 5-10x richer data than forms, and how to design one well.
How to Convert a Typeform Survey Into an AI Interview
A step-by-step migration guide. Map every Typeform question type to Koji structured questions, get AI-moderated probing, voice or text mode, and a real-time aggregated report.
Creating Your First Study
Go from a research question to a fully designed interview plan using Koji's AI Consultant.
Customer Interview Questions: 60+ Examples for Discovery, Validation, Pricing, and Churn
A reference library of 60+ proven customer interview questions for discovery, validation, pricing, NPS follow-up, and churn — plus the principles that separate questions that surface real insight from ones that produce polite lies.
Nobody Mentioned It: What Your Sample Could Not Have Detected (2026)
Silence in your interviews is not evidence a problem is rare. Here is how to compute the prevalence floor your study was blind to, and why that number belongs in every report.
Diagnostic Overshadowing: Why One Known Problem Hides Every New One (2026)
A known problem absorbs the evidence for a new one. How diagnostic overshadowing hides novel issues in feedback analysis, and four checks that detect it.
Discussion Guide Template: How to Structure Your Research Sessions
Learn how to create a research discussion guide that keeps interviews focused and uncovers deep insights. Includes templates, question structures, and how AI platforms like Koji replace static guides with adaptive conversation.
Why the Loudest Complaint Hides the Real One: Masking in Customer Interviews (2026)
One dominant complaint does not just take up airtime - it raises the threshold for everything quieter, asymmetrically, and your analysis then discards what was buried. A protocol for hearing the masked signal.
Editing the Brief Manually
How to directly edit your research brief to fine-tune questions, methodology, target audience, and more.
Your Finding Is Only Valid Inside the Range You Measured (2026)
Every research finding has a calibrated range, and the decision you need it for is usually outside that range. Hydrologists have a name and a discipline for this problem.
Why the Feature Request That Reaches You Is Bigger Than the Problem (2026)
Relayed feedback does not fade, it amplifies. The bullwhip effect explains why a request arrives louder and lumpier than the experience behind it.
Feedback Volume Tracks Attention, Not Incidence: How to Read a Complaint Trend
A rise or fall in complaint volume is at least as likely to be a change in how willing people are to report as a change in your product. Here is how to tell them apart.
The First 90 Days as a UX Researcher: A Week-by-Week Onboarding Plan (2026)
Your first 90 days set your credibility ceiling for the next two years. A concrete 30/60/90 plan for new research hires: what to audit, who to interview, which study to ship first, and the one process to change before day 90.
Forced-Choice Questions: How to Eliminate Fence-Sitting and Get Decisive Data
Forced-choice questions remove the neutral or "no opinion" escape hatch so respondents have to commit to a real preference. Learn when to use them, how to write them without bias, and how AI interviews recover the reasoning you would otherwise lose.
Generating Research Reports
Create comprehensive aggregate reports across all your interviews — including summaries, themes, recommendations, and statistics.
Green Claims Research: How to Substantiate a Sustainability Claim With Consumer Perception Evidence
Every environmental claim carries two substantiation burdens: the science burden and the perception burden. Lab data answers the first. Only research answers the second, and it is the one companies fail. Here is how to design a green claim perception study.
How Long Should User Interviews Be? Length and Duration Best Practices
How long user interviews should run by research type, with target durations for discovery, evaluative, and pulse research. Includes the science of fatigue, how AI moderation changes the math, and a calculator for picking your target length.
How to Customize AI Interview Questions: A Step-by-Step Guide
Learn how to customize AI-moderated interview questions in Koji — edit core questions, add structured question types, tune follow-up probing, and adapt your interview guide to any research goal.
The Illusion of Explanatory Depth: Why Users Explain Confidently and Wrongly (2026)
Asking users why is asking the one question people are most overconfident about. Why mechanism probes work, reason questions do not, and what to ask instead.
When the Human Baseline Is Wrong: Validating AI Analysis Against an Imperfect Gold Standard (2026)
Checking AI coding against one senior researcher does not measure accuracy - it measures agreement with that person, errors included. Here is how imperfect reference standards bias the number, which direction, and what to do instead.
Implausible Answers: Screening Self-Reported Quantities Against an Objective Ceiling (2026)
Some self-reported numbers cannot be true. Nutrition research built and validated a plausibility cutoff against an objective measure, and its verdict is that such screens grade a dataset well and convict an individual badly.
How to Improve User Interview Completion Rates
Why user interview completion rates drop, what good benchmarks look like, and the 9 concrete levers that move the rate from 40% to 80%+. Includes the AI-moderation effect, modality choice, length tuning, and incentive design.
The Assemblage and the Type Fossil: Which Quotes Actually Carry Information (2026)
Your most-mentioned theme is usually your least informative, because a signal present in every period cannot tell you which period you are in. The index-fossil test for diagnostic feedback.
What a Human Interpreter Changes in a Research Interview (2026)
Medical research has measured interpreter error precisely. The headline: an untrained bilingual helper can be worse than no interpreter at all, and omission is the most common error.
Why Your First Three Interviews Always Go Worst: The Failure-Rate Curve of an Interview Guide
Interview guides fail on a curve, not at a constant rate. Learn the three regions - early-life, useful life, and wear-out - and the opposite fixes each one needs.
Structured, Exploratory, and Hybrid: Choosing the Right Interview Mode in Koji
A complete guide to Koji's three interview modes — structured, exploratory, and hybrid — and when to use each for your research goals.
Interviewer Variance: Every Participant Answered a Slightly Different Question (2026)
Nothing is malformed, nobody lied, the arithmetic is right -- and the study is still wrong, because the stimulus was not held constant and the transcript shows a constant one.
Just-Noticeable Difference: The Smallest Product Change Users Can Actually Perceive (2026)
A change can be statistically significant and completely invisible. How Weber's law sets the smallest product change users can perceive, and how to measure your own thresholds.
Keyness: Which Words Are Actually Distinctive to a Customer Segment (2026)
Word frequency tells you what is common; keyness tells you what is distinctive. Choose a disjoint reference corpus, count each term once per document to avoid the dispersion trap Egbert and Biber documented, and read the passages before interpreting.
Koji vs Listen Labs: AI Interview Platform Comparison (2026)
An honest, side-by-side comparison of Koji and Listen Labs — pricing, features, recruitment, analysis, and which AI interview platform is the right fit for your team.
Koji vs Marvin (HeyMarvin): End-to-End AI Interviews vs. Analysis-Only Repository
Koji vs Marvin compared head-to-head. Marvin centralizes and analyzes interviews you have already conducted; Koji actually runs the interview AND analyzes it. Pricing, features, and the right pick for your team.
Lead Magnet Research: How to Create Industry Reports Using AI Interviews
How to use Koji AI interviews to gather quotable industry benchmarks and turn them into thought leadership reports, annual studies, and content marketing assets.
Why Anything You Measure Mid-Flight Looks Longer Than It Is (2026)
Sampling items that are still in progress oversamples long ones. Learn why snapshot duration estimates are inflated by variance over mean, and how to fix the frame.
Levels of Measurement: Which Statistics Each Survey Question Type Allows (2026)
Nominal, ordinal, interval and ratio data explained for customer research: the summaries each level supports, how Koji's six structured question types map onto them, and a relabelling test that catches meaningless statistics.
Likert Scale Questions: How to Use Rating Scales in User Research
A complete guide to Likert scale questions in user research — what they are, when to use them, how to write them correctly, and how Koji's AI interviews take rating scales further by pairing quantitative scores with qualitative follow-up.
The Order You Learn Things In: Context Management for Research Analysis (2026)
An analyst who knows the hypothesis before reading the transcripts reaches a different conclusion from the same data. Here is the forensic procedure that fixes it.
The List Experiment: Measure a Behavior Without Ever Asking About It (2026)
A list experiment asks people how many statements are true, never which ones. The difference between two group averages is your prevalence estimate, and no respondent is ever on record.
Longitudinal Research: How to Track User Behavior and Attitudes Over Time
Longitudinal research captures how users change over time — not just a snapshot. This guide explains panel studies, cohort studies, and how AI-moderated interviews make multi-wave research feasible for any team.
Why Your Satisfaction Score Stays Flat While Satisfaction Falls (2026)
Inbound feedback is a catch-per-unit-effort index, and those are famously hyperstable: they hold steady while the thing they measure collapses. The fisheries fix is a survey with a fixed design.
When a Readout Divides the Room: Mixed Evidence and Belief Polarization (2026)
Present mixed evidence to a divided team and both sides can report that it strengthened their position. In one controlled study the self-reports showed polarization while measured attitudes converged.
Multiple Choice Questions in AI Interviews: Capture Multi-Select Data With Conversational Depth
Learn how Koji's multiple_choice question type captures multi-select data in AI interviews — with automatic AI follow-up on each selection, stacked frequency charts, and a free-form "Other" option that gets thematically coded.
The Network Scale-Up Method: Estimating How Many, by Asking Who They Know (2026)
You cannot survey a group that will not identify itself. You can ask ordinary people how many such people they know, and scale the answer up by their network size.
Open-Ended Questions in AI Interviews: How Koji Probes Free-Form Answers for Real Depth
Learn how Koji's open_ended question type works in AI interviews — with automatic probing, theme extraction, and verbatim quote capture that goes far beyond what surveys can do.
Presupposition: The Part of Your Question Participants Cannot Decline (2026)
A leading question pushes toward an answer. A presupposing question embeds a premise the participant must accept to answer at all -- and neutral rewording does not remove it.
Reference Prices and Drip Pricing: How to Test a Price Display Without Making a Deceptive Claim
Willingness-to-pay research tells you what people will pay. It says nothing about whether your was-now price or your checkout fees are lawful. Here is the price-display law that changed in 2025 and the comprehension study that produces evidence for it.
Prize Draw Research Incentives: Free Entry Routes, Registration Rules, and the Sample You Actually Buy
Prize draws look ten times cheaper than guaranteed research incentives. Here is the lottery law that governs them in the UK and US, the four-condition free entry route, Florida registration and bonding thresholds, and the response bias you pay for instead of cash.
Randomized Response: How to Measure a Behavior Nobody Will Admit To (2026)
Randomized response adds noise to each answer on purpose, then subtracts it from the total. You get an honest population estimate and no individual ever answers the sensitive question.
Real-Time Research Insights: How to See Themes, Quotes, and Quality Scores as Interviews Complete
Stop waiting weeks for analysis — modern AI research platforms surface themes, structured-question distributions, sentiment, and quality-scored quotes the moment each interview ends. Here is how real-time research insights work in Koji and how to design studies that take advantage of them.
Referred Complaints: Why Users Blame the Feature That Is Not Broken (2026)
Users report problems at the surface they can see, not where the fault lives. How to build a referral map for your product and stop investigating healthy components.
Noise in Your Question Makes a Real Driver Look Weak (2026)
Measurement error in a predictor biases its slope toward zero. Learn why a noisy survey item understates a real driver, and how to correct for it.
When to Stop Piloting: The Defect-Decay Stopping Rule for Interview Guides
"Pilot until nothing new comes up" is not a stopping rule - the defect curve never reaches zero. Here is the economic rule that replaces it, with a worked example.
Why Your Newest Cohort Always Looks Best: Reporting Lag in Customer Feedback (2026)
A recent cohort shows fewer complaints because it has had less time to report them, not because it is healthier. How to build a development triangle for feedback data and compare cohorts at equal maturity.
Research Provenance: How to Prove an Interview, a Quote, or a Report Is Genuine (2026)
When any text can be generated, a customer quote proves nothing on its own. Content Credentials, the EU AI Act marking rules, and the hash-anchored capture method that actually works for research text.
Blanks and Spikes: Two Control Samples That Audit Your Research Instrument (2026)
Analytical labs run two different controls because there are two different ways to be wrong. A spike measures what your process misses; a blank measures what it invents. Here is how to run both on a research pipeline.
Deception and Debriefing in Research: When a Cover Story Is Justified and What You Owe Participants
Masking your hypothesis is routine and licensed. Asserting something false is a different act with a justification test, a debriefing duty, and a contamination cost you pay in every future study. Here is where the line sits and how to debrief properly.
Research Interview Template Library: 10 Proven Question Sets for Common Research Jobs
Stop starting from a blank page. This library gives you 10 ready-to-use interview question sets — for discovery, churn, onboarding, NPS follow-up, and more — each designed for Koji structured AI interviews.
No Summary Preserves Everything: What Map Projections Teach About Research Reporting (2026)
Every research summary is a projection, and the impossibility of a lossless one is a theorem rather than a craft failure. Why spot-checking quotes cannot detect the distortion, and what to publish instead.
Why a Better Analysis Cannot Rescue a Bad Sample (2026)
Sampling error has a floor that no amount of analytical care can cross. Here is the model that sets the floor, the two levers that move it, and why narrowing who you talk to beats running more interviews.
Satisficing: Why Respondents Give You Good-Enough Answers Instead of True Ones
Satisficing is the theory that explains acquiescence, straightlining, don't-know answers and response-order effects as one behaviour. Understand the mechanism and you can design it out instead of detecting it afterwards.
Scale Questions in AI Interviews: Measure NPS, CSAT, and Ratings Automatically
Learn how to configure and use scale questions in Koji AI interviews to capture NPS, CSAT, and satisfaction ratings — with automatic probing and aggregated distribution charts in your research report.
Screener Questions for User Research: A Complete Guide
Learn how to write effective screener questions that find the right research participants — and how Koji's intake forms and AI interviews make screening faster and more natural.
Digit Heaping: Why Self-Reported Numbers Pile Up on Fives and Tens (2026)
Self-reported counts cluster on multiples of 5 and 10. Heaping is measurable with Whipple's index from data you already hold, and it breaks any threshold placed on a round number.
Single Choice Questions in AI Interviews: When Radio-Style Questions Beat Free-Form
Learn how Koji's single_choice question type captures mutually exclusive answers in AI interviews — with conversational option-reading in voice mode, automatic AI probing on the chosen option, and frequency bar charts in your report.
Solicited vs Spontaneous Feedback: Why Pooling Them Corrupts Both
Feedback you asked for and feedback that arrived unasked are two different data-generating processes. Merging them into one ranked list is an arithmetic error, not a shortcut.
The Sterile Cockpit Rule for User Interviews: When to Stop Making Conversation
Aviation bans non-essential talk below 10,000 feet. User interviews have critical phases too - and most moderators are chattiest exactly when the participant needs silence.
Survey Universe: How to Define Who Counts Before You Collect a Single Answer (2026)
The universe is the population whose opinion is actually relevant to your claim. Get it wrong and no sample size, weighting or analysis can rescue the study. A protocol, four documented failures, and how to enforce it at the door.
The Taphonomy of Customer Feedback: Which Complaints Survive to Reach You (2026)
Most customer feedback is destroyed before it reaches you, and the filter has a predictable shape. A taphonomic method for naming the evidence classes your channels systematically lose.
Text Interview Experience
How text-based interviews work for participants — chat interface, streaming responses, and conversation flow.
Theme Co-Occurrence: Finding the Problems That Travel Together (2026)
The theme pair that appears together more than chance predicts is usually closer to the real problem than either theme alone. Rank pairs by observed over expected, not by raw co-occurrence, and count once per participant.
The Theme Is Real and the Percentage Is Noise: Detection vs Quantification Limits (2026)
Finding a theme and measuring how common it is are two different instruments with two different thresholds. Analytical chemistry separates them formally, and qualitative research should too.
Theme Dispersion: Why 47 Mentions Can Mean Three Customers (2026)
A mention count hides how many people produced it. 47 mentions can be 41 customers or 3. Report distinct speakers beside every count, choose your dispersion unit deliberately, and use Gries DP when the decision is expensive.
Understanding the Research Brief
A walkthrough of every section in your Koji research brief and how to read it effectively.
User Interview Software: A 2026 Buyer's Guide
How to choose user interview software in 2026 — vendor categories, evaluation criteria, pricing models, and the right pick for product, UX, marketing, and research teams.
Often, Sometimes, Rarely: Why Verbal Frequency Options Are Not Comparable (2026)
Vague frequency words carry different numeric meanings for different respondents, and the shift tracks the groups you are comparing. A measured study shows the bias can hide a real difference rather than invent one.
We Already Knew That: Why an Obvious Finding Is Not a Confirmed One (2026)
We already knew that describes how a finding feels once you have heard it, not what the team believed beforehand. The two differ measurably. Ask before you reveal.
Willingness-to-Pay Interview Template (Van Westendorp + AI)
A ready-to-clone Van Westendorp pricing interview template using Koji structured questions. Map the four price points, capture qualitative reasoning, and auto-aggregate willingness-to-pay distributions.
Nobody Mentioned It: What Zero Occurrences Actually Rules Out (2026)
Zero mentions in 20 interviews does not mean a rate of zero. The rule of three converts an absence into the only honest number: an upper bound.
Why Your Top Ten Themes Never Change (And What to Track Instead) (2026)
Theme frequencies form a steeply skewed distribution whose head is stable by construction, so a top-ten list cannot show movement. Track rank velocity, new entrants, tail mass and head concentration instead.
Writing a Research Question
Learn how to frame a clear, focused research question that sets the foundation for a successful study.