Open, Axial and Selective Coding: Strauss and Corbin's Grounded Theory Method
How Strauss and Corbin's three grounded theory coding phases work, when to use them instead of Saldaña's coding cycles, and how much data a grounded theory study needs.
What are open, axial, and selective coding?
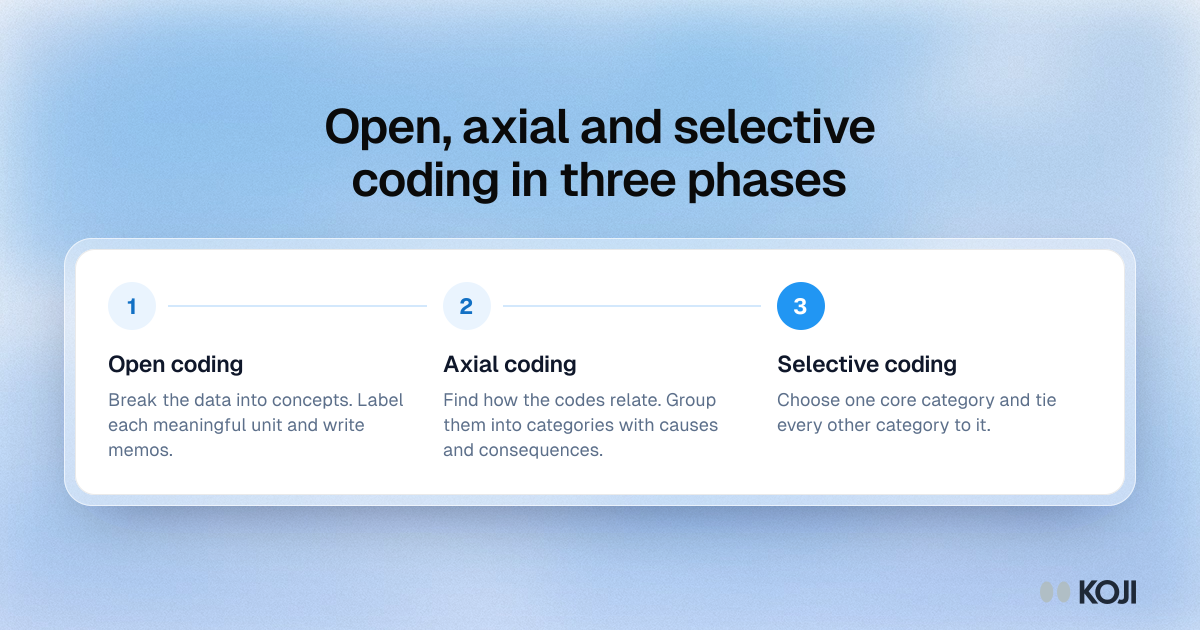
Open, axial and selective coding are the three coding phases of Anselm Strauss and Juliet Corbin's version of grounded theory, the method for building a theory from data rather than testing one. Open coding breaks the data into concepts. Axial coding works out how those concepts relate: causes, conditions, actions and consequences. Selective coding picks one core category and ties everything else to it. Use them when your goal is an explanation of a process, why people do what they do, and you are willing to collect and analyse data in rounds until that explanation holds.
This page covers the grounded theory approach specifically. If you want to code interviews to find themes, without building a theory, you don't need these phases: start with First and Second Cycle Coding, Johnny Saldaña's general method, or the beginner path in How to Code Qualitative Data.
Where the three phases come from
Barney Glaser and Anselm Strauss introduced grounded theory in The Discovery of Grounded Theory (1967). The two later split. Strauss and Corbin's Basics of Qualitative Research (1990) set out the three named phases, open, axial and selective, and added a fixed set of questions for axial coding, the "coding paradigm". Glaser rejected both. In Emergence vs Forcing (1992) he argued that the paradigm makes researchers force data into a ready-made structure instead of letting a theory emerge.
The debate still shapes how people teach the method. Udo Kelle's review of it, in Forum Qualitative Sozialforschung, gives a fair summary:
Glaser's critique "points out some existing weaknesses of Strauss' concepts but vastly exaggerates the risks of the Straussian approach." (Udo Kelle, Forum Qualitative Sozialforschung, 2005)
In practice there are three main schools: Glaser's classic grounded theory (open, selective and theoretical coding), Strauss and Corbin's (open, axial, selective), and Kathy Charmaz's constructivist grounded theory (initial, focused and theoretical coding). This page follows Strauss and Corbin, because theirs is the one with the three phases most people search for.
Grounded theory coding or Saldaña's cycles?
Most product and UX studies don't need grounded theory. They need well-coded themes that answer a question the team already has. Grounded theory earns its extra work when nobody yet understands the process you are studying, and when you can keep recruiting based on what you learn.
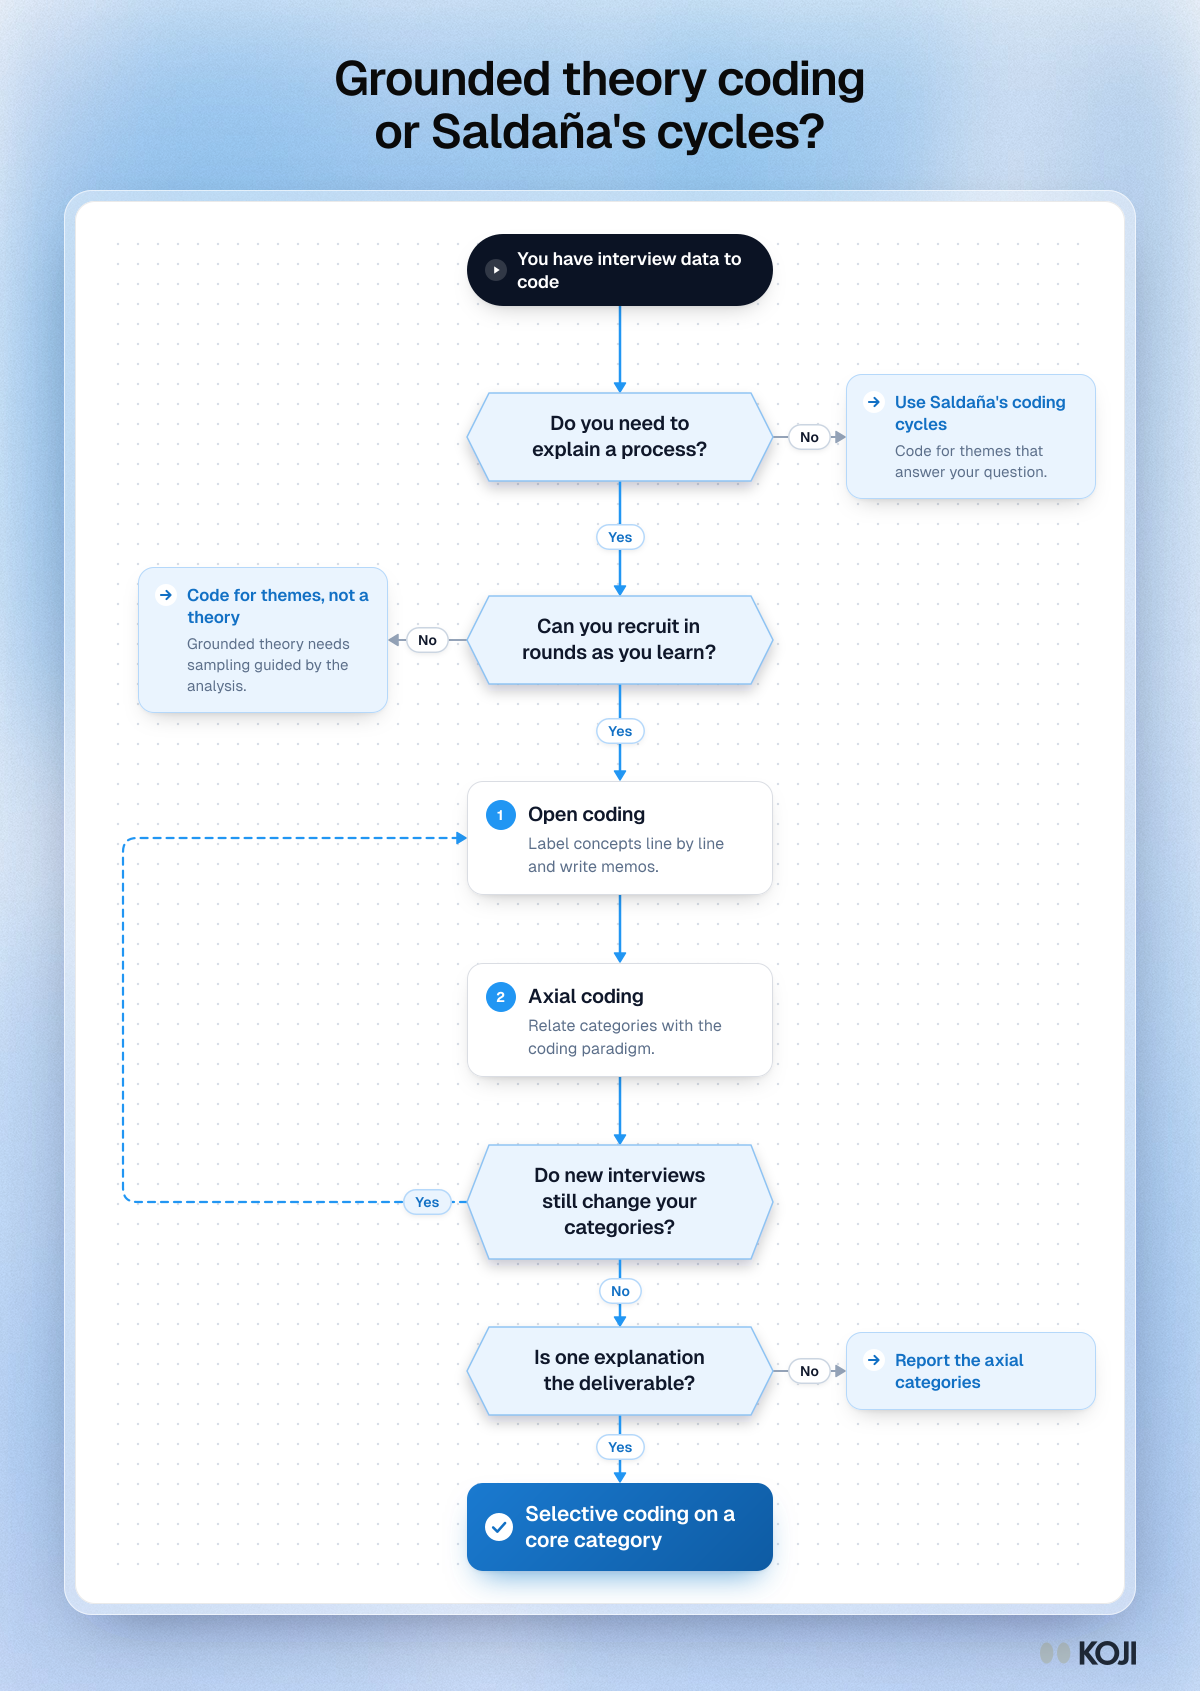
| Grounded theory (Strauss and Corbin) | Saldaña's first and second cycles | |
|---|---|---|
| Goal | A theory that explains a process | Codes and themes that answer a question |
| Sampling | In rounds, guided by the emerging theory | Usually planned up front |
| Coding | Open, axial, selective, alongside data collection | First cycle, then second cycle, often after collection |
| Output | One core category and how others relate to it | A set of themes with evidence |
| Best for | New or poorly understood processes, academic work | Most product, UX and customer research |
Phase 1: Open coding
Open coding is the first pass through your data, where you read line by line and label each meaningful unit with a short code. The goal is breadth: capture every concept, action or meaning you see, without committing to categories.
How it works
- Read the data once without coding. Interview transcripts, field notes, open survey answers. Get a feel for the whole.
- Go through again, line by line. For each meaningful chunk, write a short code that says what is happening. Codes can be:
- Descriptive: "first-time login confusion"
- In vivo, using the participant's exact words: "the dashboard is overwhelming" (see In Vivo Coding)
- Process: "deciding whether to upgrade"
- Keep codes provisional. Don't merge yet. Many codes at this stage is normal.
- Write memos. When a code feels important or unclear, write a paragraph on what you saw. Memos carry your reasoning into axial coding. See Analytic Memos.
- Compare as you go. Each new passage is compared with the ones already coded. This is the constant comparative method, the engine of all three phases.
Open coding example
Suppose you ran six interviews about how product managers prepare for stakeholder reviews. A passage like:
"I usually rebuild my deck from scratch the morning of, even though I have a template, because I never feel like the template covers what this particular VP cares about."
might produce open codes like:
- last-minute deck rebuilding
- template not fitting audience
- VP-specific preferences
- avoiding template reuse
- morning-of-review preparation
The codes are granular and overlap. That is fine in open coding.
Common open coding mistakes
- Coding too sparsely. One code per page is summarising, not coding.
- Bringing in categories you already hold. If you already "know" the themes, you will only see those.
- Merging too early. "Confusion" and "frustration" feel close but may have different causes. Keep them apart until axial coding shows whether to merge.
- Skipping memos. A list of codes without memos loses the reasoning behind each label.
Phase 2: Axial coding
Axial coding takes the codes from open coding and works out how they relate: what causes what, under which conditions, and with what result. The output is a smaller set of categories, each with subcategories that explain how the codes beneath it connect.
Strauss and Corbin's coding paradigm
The coding paradigm asks six questions of each category:
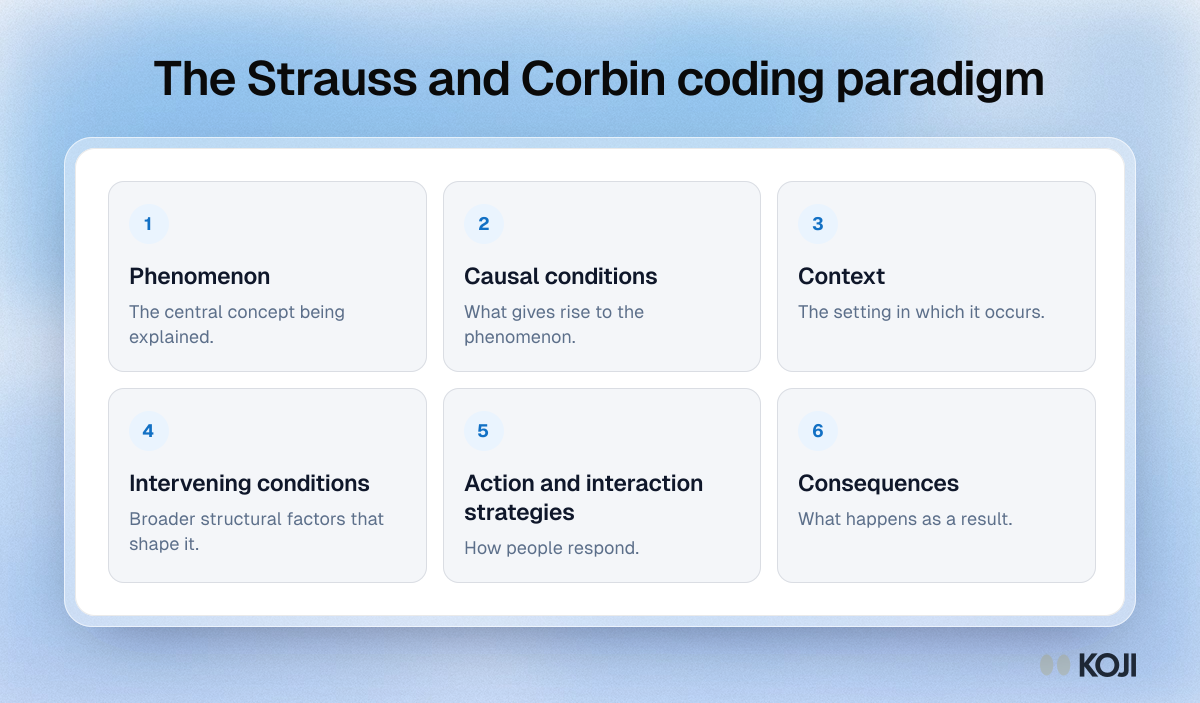
- Phenomenon: the central idea being explained.
- Causal conditions: what gives rise to it.
- Context: the setting in which it happens.
- Intervening conditions: wider factors that shape it.
- Action and interaction strategies: how people respond.
- Consequences: what happens as a result.
Use the paradigm as a set of prompts, not a form to fill in. This is exactly where Glaser's "forcing" charge bites: if you fill all six boxes for every category whether the data supports it or not, you are imposing structure. Leave a box empty when the data is silent.
Axial coding example
Using the open codes above, axial coding might give:
Category: Audience-fit anxiety in stakeholder presentations
- Causal conditions: generic templates, varied stakeholder priorities
- Context: high-stakes review meetings, little prep time
- Intervening conditions: no stakeholder profile data, no shared template library
- Action strategies: last-minute rebuilding, asking peers for the latest version, padding decks with backup slides
- Consequences: late nights, repeated slides, lower confidence
Now you have a category with structure, not just a list of codes. A reader can follow the causal logic.
When to move from open to axial
Move when new interviews add few new open codes, when codes start to cluster around recognisable ideas, and when your memos already hint at relationships. In practice the two phases overlap, and most researchers go back and forth. See Data Saturation.
Phase 3: Selective coding
Selective coding is the final phase, where you choose one core category, the concept that explains the most about your data, and integrate every other category around it. This is where grounded theory earns its name: the result is a theory grounded in the data.
How to identify the core category
The core category should:
- appear often in the data
- connect to all or most other categories
- explain variation across cases
- be abstract enough to apply widely and concrete enough to feel grounded
- explain why participants did what they did
Selective coding example
From the stakeholder study, the axial categories might be audience-fit anxiety, template-tool mismatch, time pressure that cascades, and gaps in learning across teams. A candidate core category: "the gap between generic preparation tools and audience-specific expectations." Each axial category becomes a facet of it. Audience-fit anxiety is how it feels, the template mismatch is the cause in the artefacts, cascading time pressure is the consequence over time, and the learning gaps are the structural condition.
When selective coding is too ambitious
Forcing a core category onto thin data produces a theory that overreaches. For a sprint-sized study, stop at well-structured axial categories. Go on to selective coding when the decision you are informing is large, when a single explanation is the deliverable, and when you have enough data to support it.
How much data grounded theory needs
There is no fixed number, because grounded theory samples until the theory is saturated. The published guidance gives a sense of scale:
- John Creswell suggests 20 to 30 interviews for a grounded theory study (Creswell, 1998), and Janice Morse suggests 30 to 50 (Morse, 1994).
- Hennink, Kaiser and Marconi (2017) found that the range of issues was covered by nine interviews, but 16 to 24 were needed to understand what those issues meant, which is the depth a theory needs.
- Hagaman and Wutich (2017) found that 16 or fewer interviews were enough for themes within one fairly similar site, but 20 to 40 were needed for themes that held across four sites.
The pattern is the same in all of them: finding the topics is quick, explaining them takes longer, and explaining them across different groups takes longer still. For more detail, read Interview Sample Size Research.
Can AI do grounded theory coding?
Partly. A 2025 tutorial in the Journal of Medical Internet Research compared ChatGPT-assisted grounded theory coding with manual coding of the same interviews. The authors found that the AI-assisted coding improved the efficiency and variety of codes, but was weaker than manual coding on depth, context, connections between codes and how codes were organised (Yue et al., 2025).
That matches the shape of the method. AI is useful for the breadth of open coding and for suggesting groupings. The relational work of axial coding and the choice of a core category depend on judgment about the whole study, and that stays with the researcher.
How Koji helps
Koji is built for interview studies, and it fits the open coding and early axial stages of grounded theory well:
- Rounds of interviews without scheduling. Koji runs AI-moderated interviews by voice or text and asks follow-up questions on open answers. Because there are no calls to book, you can run a round, read it, change your questions to follow the emerging theory, and run the next round. That is theoretical sampling at a pace a small team can manage.
- An open coding pass on every answer. After each interview, Koji codes each answer with short labels about its meaning and attaches the participant's exact words to each one. Quotes are checked against the transcript, and a code that can't be grounded is dropped.
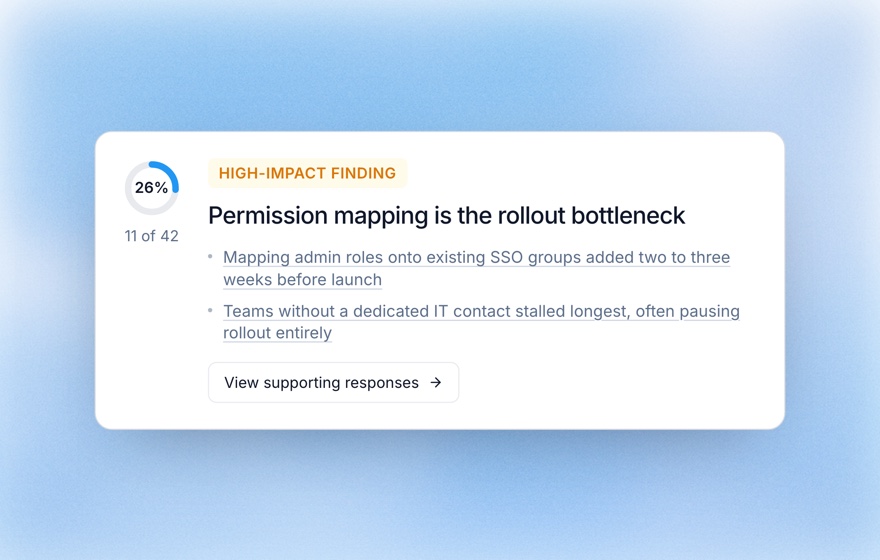
- Codes grouped across interviews. The report groups similar codes from different interviews into themes for each question, with how many interviews mention each. Treat these as candidate categories for axial coding, not as the categories themselves.
- Evidence you can trace. Every finding opens to the quotes behind it and back to the transcript, so you can test a category against the data, which is the point of constant comparison.
- Interview quality ratings. Each interview gets a quality rating with scores for relevance, depth, coverage and completion, which helps you find the rich interviews to read in full first.
Koji does not do axial or selective coding for you. Applying the coding paradigm and choosing a core category is your work, done with the memos you write and the transcripts you read.
A practical workflow
- Run a first round of 8 to 10 interviews in Koji, with open questions about the process you want to explain.
- Read three to five transcripts in full and write memos.
- Use Koji's codes and themes as a check on your own open codes: what did you miss, what did it group that you would keep apart?
- Apply the coding paradigm to your strongest categories and note the gaps.
- Change the interview questions to probe those gaps and run the next round.
- Repeat until new rounds stop changing your categories, then decide whether the study needs a core category.
- Write it up with the core category as the spine. See Research Storytelling.
Frequently asked questions
Do I need all three phases for every study? No. Open and axial coding are enough for most product and UX research. Selective coding suits academic work or large strategic studies where a single explanation is the deliverable.
What is the difference between grounded theory coding and thematic analysis? Grounded theory aims to build a theory and collects data in rounds guided by the analysis. Thematic analysis, popularised by Braun and Clarke, aims to find and report patterns, and usually works on data already collected. See the Thematic Analysis Guide.
What is the difference between Strauss and Corbin's and Glaser's grounded theory? Strauss and Corbin use open, axial and selective coding with a fixed coding paradigm. Glaser uses open, selective and theoretical coding and rejects the paradigm as forcing structure onto data.
Can AI do grounded theory coding for me? It can speed up open coding and suggest groupings. A 2025 JMIR tutorial found AI-assisted coding weaker than manual coding on depth, context and connections, which is the heart of axial and selective coding.
What is in vivo coding? In vivo coding uses participants' exact words as codes, for example "the dashboard is overwhelming" instead of "interface complexity". In grounded theory it is common in open coding, and in vivo codes often name categories later.
How many interviews does grounded theory need? There is no fixed number. Published guidance ranges from 20 to 30 (Creswell) to 30 to 50 (Morse), and you stop when new interviews no longer change your categories.
Related resources
- First and Second Cycle Coding: the general coding method, and where open, axial and theoretical coding sit among Saldaña's methods.
- Grounded Theory in Qualitative Research: the full methodology these phases belong to.
- The Constant Comparative Method: the comparison process that drives open and axial coding.
- How to Build a Qualitative Research Codebook
- Framework Analysis: a structured alternative when you have set questions to answer.
- Structured Questions Guide
Sources
- Glaser, B. G., & Strauss, A. L. (1967). The Discovery of Grounded Theory. Aldine.
- Strauss, A., & Corbin, J. (1990). Basics of Qualitative Research. SAGE.
- Glaser, B. G. (1992). Basics of Grounded Theory Analysis: Emergence vs Forcing. Sociology Press.
- Kelle, U. (2005). "Emergence" vs. "Forcing" of Empirical Data? A Crucial Problem of "Grounded Theory" Reconsidered. Forum Qualitative Sozialforschung, 6(2), Art. 27.
- Creswell, J. W. (1998). Qualitative Inquiry and Research Design. SAGE.
- Morse, J. M. (1994). Designing funded qualitative research. In Handbook of Qualitative Research. SAGE.
- Hennink, M. M., Kaiser, B. N., & Marconi, V. C. (2017). Code saturation versus meaning saturation. Qualitative Health Research, 27(4), 591–608.
- Hagaman, A. K., & Wutich, A. (2017). How many interviews are enough to identify metathemes in multisited and cross-cultural research? Field Methods, 29(1), 23–41.
- Yue, Y., et al. (2025). A Practical Guide and Assessment on Using ChatGPT to Conduct Grounded Theory: Tutorial. Journal of Medical Internet Research, 27, e70122.
Further reading on the blog
- How to Analyze Customer Interview Data: A Complete Guide — You ran the interviews. Now what? Here is a step-by-step process for turning raw transcripts into clear, actionable insights your team will
Related Articles
How to Code Qualitative Data: Your First Coding Pass on 10 Interviews
The beginner path to coding qualitative data: one complete coding pass on ten interview transcripts, from first codes to checked themes, with a worked example.
The Constant Comparative Method: A Step-by-Step Guide
How the constant comparative method works: Glaser and Strauss's four stages, a product research example, how to know when to stop, and common mistakes.
Data Saturation in Qualitative Research: How to Know When You Have Enough
Data saturation is the point at which additional interviews stop producing new information. This guide covers the four types of saturation (theoretical, data, code, meaning), how to recognize and document them, the empirical sample sizes from Hennink and Guest, and how AI-moderated interviews let you reach saturation in days instead of months.
First and Second Cycle Coding: Saldaña's Coding Methods Explained
The two cycles of qualitative coding from Saldaña's Coding Manual: first cycle methods, second cycle methods such as pattern coding, a worked example and how to choose.
Framework Analysis: The Complete Guide to the Matrix Method for Qualitative Data (2026)
A step-by-step guide to framework analysis (the Framework Method) for qualitative research — the five stages, the charting matrix, when to use it, and how AI speeds it up.
Grounded Theory in Qualitative Research: A Practical Guide
A practical guide to grounded theory methodology — how to collect, code, and analyze qualitative data to develop theory from the ground up, and how AI-powered tools accelerate the iterative analysis process.
Qualitative Data Analysis Software: The AI-Native Alternative to NVivo and ATLAS.ti (2026)
A practical guide to qualitative data analysis (QDA) software in 2026 — what it does, how legacy CAQDAS tools like NVivo and ATLAS.ti compare, and why AI-native platforms like Koji collapse coding, theming, and reporting into one automated workflow.
Research Synthesis: How to Combine Multiple Studies Into Clear Insights
A practical guide to synthesizing findings across multiple research studies — using thematic synthesis, triangulation, and structured data aggregation to build compounding organizational knowledge.
Structured Questions in AI Interviews
Mix quantitative data collection — scales, ratings, multiple choice, ranking — with AI-powered conversational follow-up in a single interview.
The Complete Guide to Thematic Analysis
Learn how to systematically analyze qualitative data using Braun and Clarke's six-phase thematic analysis framework.
Verbatim Analysis: How to Code and Analyze Open-Ended Responses at Scale (2026)
Verbatim coding turns messy open-ended answers into countable themes — but manual coding is slow, expensive, and bias-prone. Learn the code-frame workflow, the manual vs AI tradeoff, and how Koji auto-codes verbatims and captures the depth a survey verbatim never could.