Interview Sample Size Research: What the Saturation Studies Found
The evidence behind interview sample sizes: what Guest (2006), Namey (2016), Hennink (2017) and Creswell found about saturation, and how far each applies to product research.
The short answer: the best-known studies found that about 6 interviews with a similar group surface most of the main themes, about 12 reach saturation for high-level themes, and 16 to 24 are needed to understand each theme in depth (Guest, Bunce and Johnson 2006; Hennink, Kaiser and Marconi 2017). This page is the evidence behind those numbers: what each study did, what it found and how far it applies to product research.
For the full planning guide (sample sizes by research goal, segment and method), read How Many User Interviews Do You Need?. For deciding when to stop during a study, see Data Saturation in Qualitative Research. Founders sizing validation work should read How Many Customer Interviews Does a Founder Need?.
The Short Answer
For most qualitative research projects with a reasonably homogeneous participant group:
- 6 interviews will surface the most prominent themes
- 12 interviews will get you to thematic saturation for most topics
- 15–20 interviews may be needed for highly diverse populations or complex topics
These numbers come from real research, which we'll walk through below.
What Is Saturation?
Saturation is the point at which additional interviews stop generating fundamentally new insights. You're still hearing stories and details, but the core patterns have stabilized — new data confirms existing themes rather than introducing new ones.
The concept was introduced by Barney Glaser and Anselm Strauss in 1967 as part of grounded theory, but it's since become the standard criterion for sample adequacy across qualitative methods.
Saturation doesn't mean you've learned everything there is to know. It means the return on investment of each additional interview has dropped below a practical threshold.
What the Research Says
Guest, Bunce, and Johnson (2006)
This landmark study is the most frequently cited empirical investigation of saturation. The researchers analyzed 60 in-depth interviews from a study in West Africa and tracked when new themes emerged.
Their findings:
- 73% of all themes were identified within the first 6 interviews
- 92% of themes were identified within the first 12 interviews
- After 12 interviews, new themes emerged at a very low rate
Their recommendation: For studies with a fairly homogeneous population, a sample of 12 is generally sufficient to reach saturation for high-level thematic analysis. For more granular, detailed coding, more interviews may be needed.
Creswell (2013)
John Creswell, one of the most widely cited qualitative methodology scholars, provides the following general guidelines in his textbook Qualitative Inquiry and Research Design:
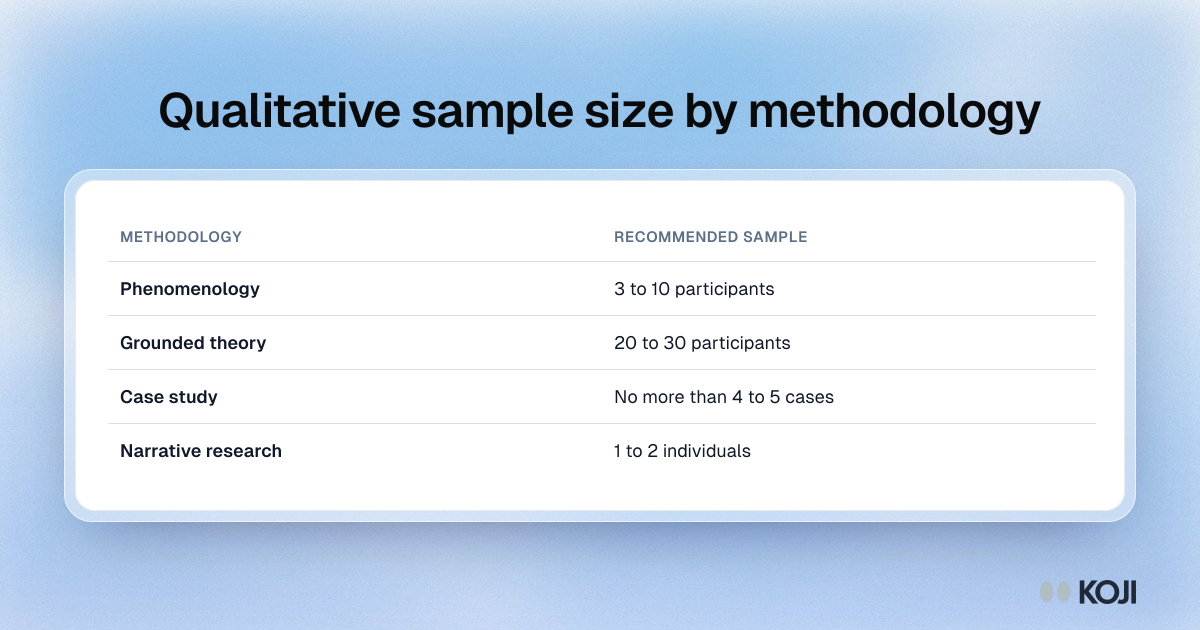
| Methodology | Recommended Sample Size |
|---|---|
| Phenomenology | 3–10 participants |
| Grounded theory | 20–30 participants |
| Case study | No more than 4–5 cases |
| Narrative research | 1–2 individuals |
Creswell gives no range for generic thematic analysis, which is what most product research uses. For that, the saturation studies below are the better guide.
Hennink, Kaiser, and Marconi (2017)
This study distinguished between two types of saturation:
- Code saturation — the point where no new codes emerge (typically reached by 9 interviews)
- Meaning saturation — the point where you fully understand the dimensions and nuances of each code (typically reached by 16–24 interviews)
This distinction is practically important: if you need broad themes to guide a product direction, 9–12 interviews may suffice. If you need deep understanding of a specific behavior for detailed design, you might need 16 or more.
Namey et al. (2016)
This study compared 40 individual interviews with 40 focus groups, resampling them to simulate many smaller studies. It found that 8 individual interviews reached 80% thematic saturation and 16 reached 90%, and that individual interviews were more cost-effective than focus groups for reaching saturation.
Factors That Affect Your Sample Size
The right number of interviews depends on several factors:
Population Homogeneity
| Population Type | Description | Typical Sample Needed |
|---|---|---|
| Highly homogeneous | Similar role, company size, industry, experience level | 6–10 interviews |
| Moderately homogeneous | Same role but different industries or company sizes | 10–15 interviews |
| Heterogeneous | Different roles, industries, or experience levels | 15–25 interviews |
The more similar your participants are, the faster you'll reach saturation. If you're interviewing senior product managers at enterprise SaaS companies, 8–10 interviews will likely be sufficient. If you're interviewing "anyone who has used a project management tool," you'll need many more.
Scope of Research Questions
Narrow, focused research questions saturate faster than broad, exploratory ones.
- "How do PMs at companies with 50–200 employees prioritize their backlog?" — Narrow; likely saturates by 8–10
- "How do people manage work across multiple tools?" — Broad; may need 15–20
Data Richness Per Interview
Longer, more in-depth interviews (45–60 minutes) generate richer data per session. You may need fewer interviews if each one is substantial. Short, shallow interviews (15–20 minutes) require more participants to reach the same depth.
Analysis Method
Basic thematic analysis requires fewer interviews for saturation than detailed grounded theory or phenomenological analysis. For most product research, basic to moderate thematic analysis is appropriate. Learn more in our thematic analysis guide.
A Practical Decision Framework
Here's a practical framework for deciding your sample size:
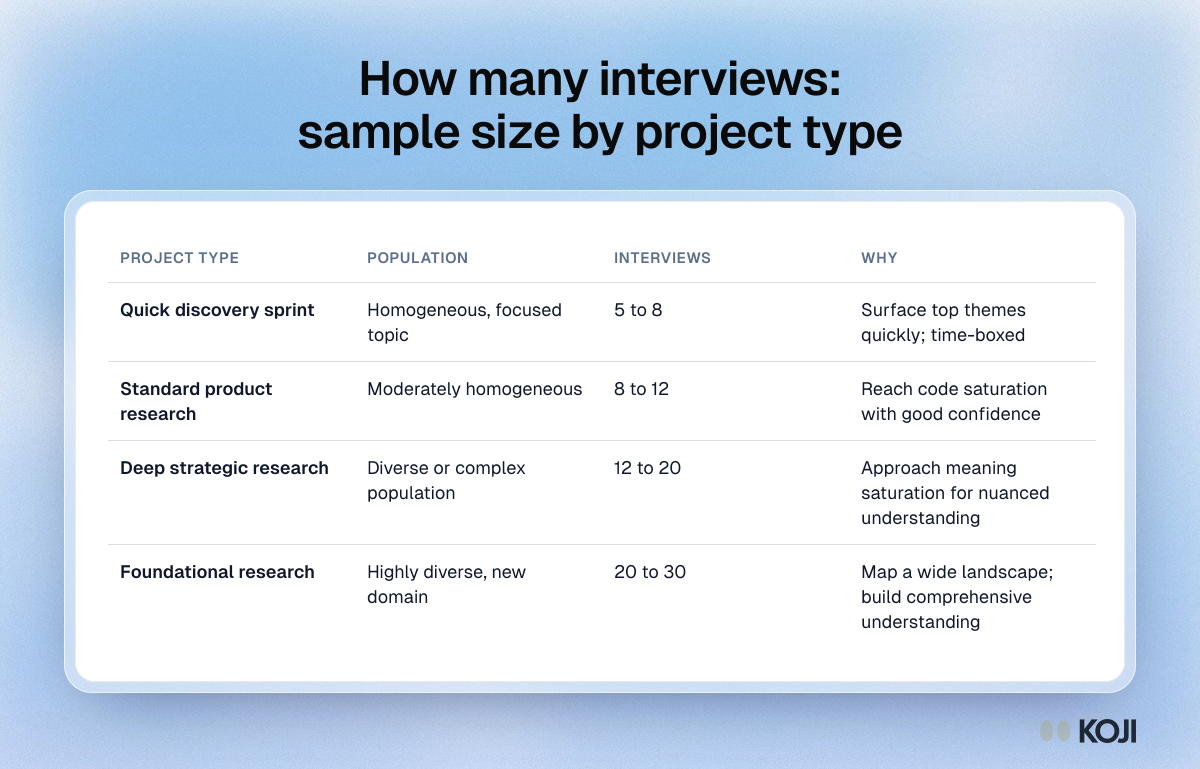
| Project Type | Population | Recommended N | Reasoning |
|---|---|---|---|
| Quick discovery sprint | Homogeneous, focused topic | 5–8 | Surface top themes quickly; time-boxed |
| Standard product research | Moderately homogeneous | 8–12 | Reach code saturation with good confidence |
| Deep strategic research | Diverse or complex population | 12–20 | Approach meaning saturation for nuanced understanding |
| Foundational research | Highly diverse, new domain | 20–30 | Map a wide landscape; build comprehensive understanding |
How to Know When You've Reached Saturation
In practice, you can track saturation in real time:
- After each interview, note the new insights (things you hadn't heard before)
- Track the rate of new themes emerging per interview
- When 2–3 consecutive interviews produce no fundamentally new themes, you're likely at code saturation
This doesn't need to be formal. A simple tally of "new things I learned" per interview gives you a practical saturation curve.
With Koji, this process becomes even more visible — as the platform analyzes each interview, you can see themes building and stabilizing across your dataset. When the theme map stops changing meaningfully with new interviews, you know you're approaching saturation.
The Case for Starting Small
A pragmatic approach is to plan for 8 interviews initially, with the option to extend:
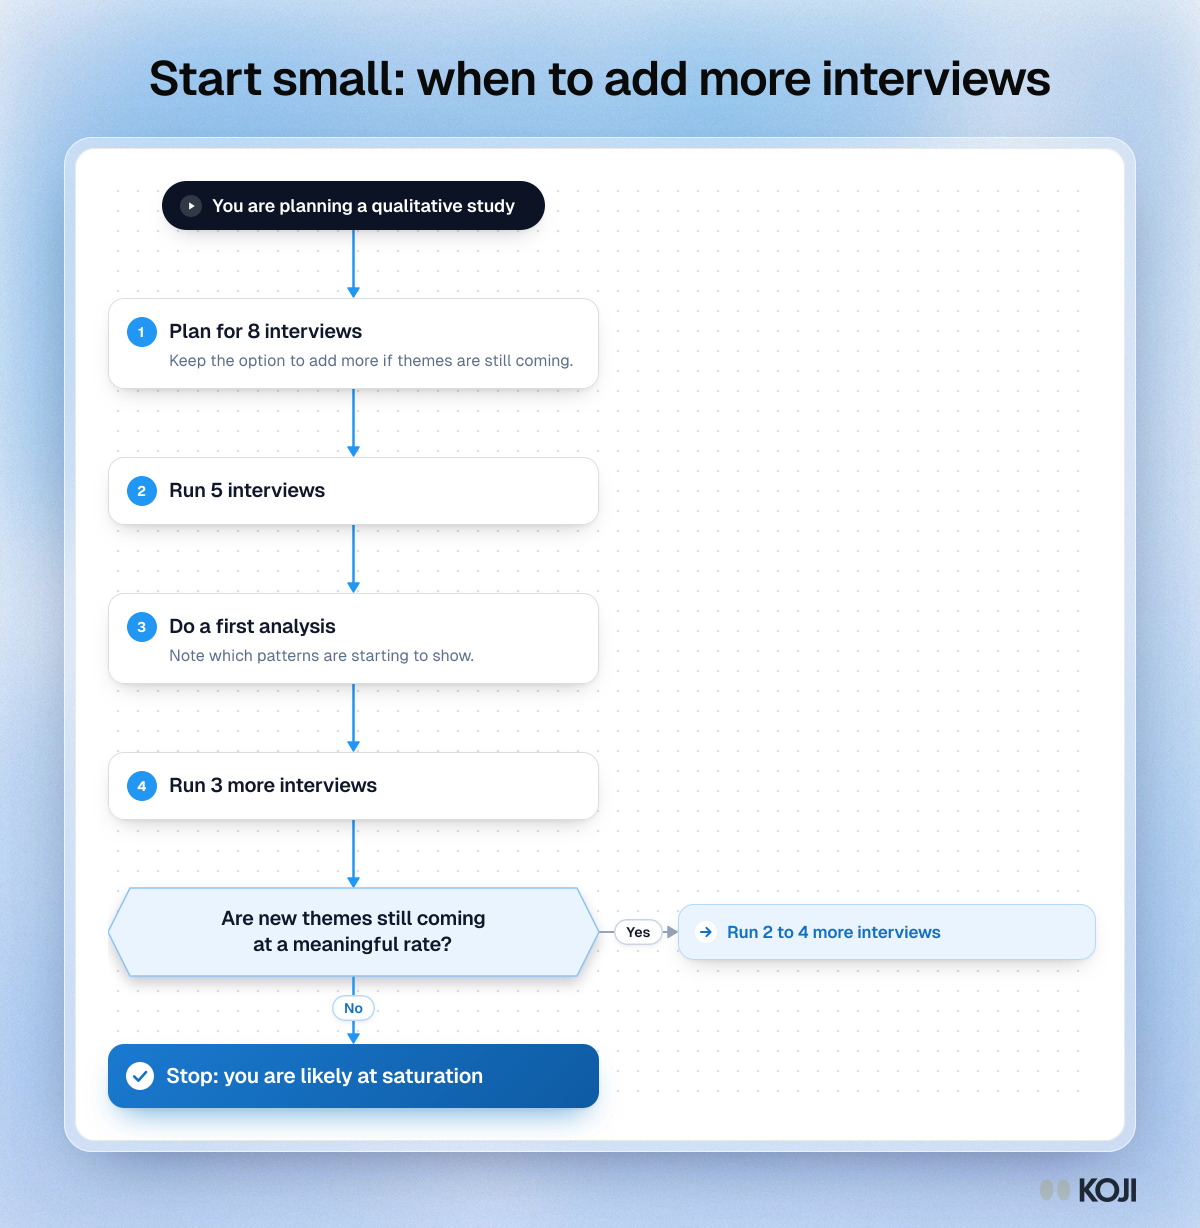
- Conduct 5 interviews
- Do a preliminary analysis — what patterns are emerging?
- Conduct 3 more interviews
- Check: are new themes still emerging at a meaningful rate?
- If yes, conduct 2–4 more. If no, you're likely at saturation.
This iterative approach avoids both under-researching (too few interviews to be confident) and over-researching (diminishing returns on time investment).
Defending Your Sample Size to Stakeholders
Stakeholders from quantitative backgrounds often challenge qualitative sample sizes. Here's how to respond:

Photo by Vitaly Gariev on Unsplash
- Different purpose, different rules. Qualitative research aims for depth and understanding, not statistical generalizability. The goal is to understand why, not to measure how many.
- Cite the research. Guest et al. (2006) demonstrated that 12 interviews capture 92% of themes for a homogeneous group. This is peer-reviewed, reproducible evidence.
- Frame it practically. "After 10 interviews, we stopped hearing fundamentally new problems. Adding more interviews would add nuance but not change our strategic recommendations."
- Compare the alternatives. A survey of 500 people will tell you 73% find onboarding confusing. Ten interviews will tell you exactly why, where, and how to fix it.
Further Reading
- How Many User Interviews Do You Need?: the full sample-size planning guide
- Data Saturation in Qualitative Research: how to tell when to stop
- User Interview Guide — the complete interview methodology
- Finding Research Participants — recruit the right people for your study
Further reading on the blog
- Best AI Market Research Tools in 2026: The Complete Buyer's Guide — AI has fundamentally changed market research. This guide compares the leading AI market research platforms—from AI-native interview tools li
- AI-Moderated vs Human-Moderated Interviews: Which Should You Choose? — AI-moderated and human-moderated interviews each have a time and a place. Here is the honest comparison to help you choose the right approac
- Best AI Customer Interview Tools in 2026: The Complete Buyer's Guide — AI has fundamentally changed how product teams conduct customer research. Here are the best AI customer interview tools in 2026 — ranked by
Related Articles
B2B vs B2C Customer Research: Key Differences and How to Run Each (2026)
How B2B and B2C customer research differ across sample size, recruiting, buying units, depth, and cadence — plus how to run each well and why AI interviews fit both the hard-to-reach B2B buyer and the high-volume B2C audience.
Continuous Discovery: How to Run Weekly Customer Interviews Without Burning Out
Continuous discovery is the practice of conducting customer interviews every week as part of your normal workflow. This guide explains how to build an always-on research practice that actually scales.
Crossdating Customer Stories: Placing an Account by Pattern, Not by Counting (2026)
Tenure and adoption counts are ring counts with no internal check. How dendrochronology places a sample by matching its pattern against a master chronology, and how to build one for accounts.
Customer Discovery Interviews: The Complete Guide
Learn how to conduct customer discovery interviews to validate your product ideas before building. Covers Steve Blank methodology, question frameworks, sample sizes, and common mistakes.
Nobody Mentioned It: What Your Sample Could Not Have Detected (2026)
Silence in your interviews is not evidence a problem is rare. Here is how to compute the prevalence floor your study was blind to, and why that number belongs in every report.
Why the Loudest Complaint Hides the Real One: Masking in Customer Interviews (2026)
One dominant complaint does not just take up airtime - it raises the threshold for everything quieter, asymmetrically, and your analysis then discards what was buried. A protocol for hearing the masked signal.
How to Prove There Is No Difference: Equivalence Testing for Product Research (2026)
A non-significant result does not mean there is no difference - it usually means your study could not tell. Equivalence testing is the method that lets you actually claim two things are the same, and product teams make expensive no-difference decisions without it every quarter.
How to Find and Recruit Research Participants
A practical guide to sourcing, screening, and scheduling the right participants for your qualitative research study.
Focus Group Research: The Complete Guide
Learn when to use focus groups, how to design and moderate them, and when AI-powered individual interviews are a better fit.
Futility Analysis: How to Decide a Running Study Will Never Answer Your Question
Most teams only ever ask whether a study can be stopped early because it worked. The more valuable question is whether it can be stopped because it never will. Futility rules, stop-for-harm, and who is allowed to make the call.
Interim Analysis and Stopping Rules: How to Stop a Study Early Without Faking the Result (2026)
Clinical trials solved the problem of looking at data before a study ends. Group sequential designs, alpha spending, and futility boundaries let you stop early without inflating false positives - and the evidence shows what happens when you stop early without them.
Why Your First Three Interviews Always Go Worst: The Failure-Rate Curve of an Interview Guide
Interview guides fail on a curve, not at a constant rate. Learn the three regions - early-life, useful life, and wear-out - and the opposite fixes each one needs.
Why Anything You Measure Mid-Flight Looks Longer Than It Is (2026)
Sampling items that are still in progress oversamples long ones. Learn why snapshot duration estimates are inflated by variance over mean, and how to fix the frame.
How to Validate Product-Market Fit Through Qualitative Interviews
Learn how to design and run customer interviews specifically focused on measuring and moving your product-market fit score.
Levels of Assurance in Research: How Much Confidence a Study Can Honestly Support
Auditing defines three levels of assurance - reasonable, limited, and none. Research reports use one voice for all three. Here is how to pick and state the level before you field a study.
Why a Better Analysis Cannot Rescue a Bad Sample (2026)
Sampling error has a floor that no amount of analytical care can cross. Here is the model that sets the floor, the two levers that move it, and why narrowing who you talk to beats running more interviews.
Startup Idea Validation: How to Test Your Idea with Customer Interviews
A research-backed guide to validating startup ideas through customer interviews — before you write a line of code.
Survey Data Quality: How to Detect and Prevent Bad Responses (2026)
The threats that corrupt survey data — straightlining, speeding, bots, fraud, and inattentive respondents — how to detect and prevent each, and why conversational AI interviews are structurally resistant to the junk that plagues panel surveys.
Surveys vs. Interviews: How to Choose the Right Research Method
A comprehensive comparison of surveys and interviews as research methods. Understand when to use each, the key trade-offs, how to combine them in mixed-methods studies, and why the choice matters for research quality.
The Theme Is Real and the Percentage Is Noise: Detection vs Quantification Limits (2026)
Finding a theme and measuring how common it is are two different instruments with two different thresholds. Analytical chemistry separates them formally, and qualitative research should too.
Why Your Theme Discovery Curve Flattens: Dependent Samples and the Illusion of Saturation (2026)
A flat theme curve measures your recruiting as much as your coverage. When both passes come from one channel, reported coverage rises to 99 percent while real coverage falls to 66.
How to Conduct Usability Testing: The Complete Guide
A comprehensive guide to usability testing for UX researchers and product managers. Covers types of testing, participant numbers, step-by-step facilitation, and the most common mistakes to avoid.
The Definitive Guide to User Interviews
Everything you need to plan, conduct, and analyze user interviews that produce actionable research insights.
Nobody Mentioned It: What Zero Occurrences Actually Rules Out (2026)
Zero mentions in 20 interviews does not mean a rate of zero. The rule of three converts an absence into the only honest number: an upper bound.